Important: Schema change delayed to May 23

With our ongoing hosting issues due to massive traffic increases and failing hardware we’ve been too distracted trying to manage those issues to finish all of the testing for the schema change release that was scheduled for today.

We deeply regret having to do this, but we’re going to delay the schema change release by a week. It is now scheduled for May 23, 2016. This week long delay will give us a chance to further tweak our server configuration (more on this in the next blog post) and to test the schema change release in much more detail.

We are, however, going to upgrade our database server to Postgres 9.5 either later today or tomorrow. During this upgrade we are going to employ a back-up database server and keep MusicBrainz running in read-only mode with a slightly reduced overall capacity (I’m sure everyone know what that means by now). This upgrade should have no other effects on our downstream data users.

We will give people plenty of notice before we start the postgres upgrade via our site banner and via our Twitter account (@musicbrainz).

Sorry for the continued drama affecting our services — we’re working hard to keep things together!

Important information about the May 16 schema change release

In the past few weeks we’ve been hit with massive increases in traffic and a couple of hardware failures. Trying to maintain a decent service quality in light of both of these events have taken a lot of time of our team and we don’t feel 100% confident about the schema change release tomorrow.

Fortunately, the entire team will be together in one place tomorrow. The first thing we’re going to do is review the current state of affairs and decide how to tackle the Postgres upgrade and the release. As soon as we have our plan put together, we will post an updated blog entry with all of the needed details. But, we may very well delay the release by 24 hours.

However, we found that we ran out of time on one feature: MBS-6024: Support more than one barcode on same release. This one ticket will not be included in the upcoming release. We’re really sorry for letting that one issue slip — sorry for any inconvenience this may cause you.

Temporary autoeditor election procedure

Hello people,

In former days, new autoeditor elections were announced on the autoeditor mailing list that all autoeditors were automatically subscribed to. However, all our mailing lists, including the autoeditor one, died in September 2015 when the server they were hosted on took its last breath. This effectively halted the election of new autoeditors. It was always the plan that our new forums should be able to handle this, but our recent issues have meant development on the features necessary to completely replace the autoeditor mailing list has been slow. Thus Nicolás (reosarevok) and I had a talk about how to handle elections going forward, and we came up with this procedure:

  1. The proposer nominates the editor normally (starting an election), and then adds a post in the Autoeditors category of the forum linking to the election and asking for seconders. Like with the mailing list, this should also contain the proposer’s reasoning for proposing the candidate.
  2. Nicolás (reosarevok) will then mail out to all autoeditors with a link to the election topic (and possibly a link to this blog post).
  3. The proposer, Nicolás or me (or another autoeditor, if they’re faster) will update the thread once a 2nd seconder is found and the voting has started, and again when the voting has ended and the results are in.

We have added most autoeditors who are already signed up on the new forums to the @MB_Autoeditors group, but not all autoeditors have signed in to Discourse yet, and some have spaces or other “weird” characters in their username that make Discourse not able to parse them. If you find that you’re not in the @MB_Autoeditors group and you think you should be, please write a message to me (Freso) or Nicolás (reosarevok) via MusicBrainz and ask us to add you to the group. (Sending your message via MusicBrainz will let us know that it is indeed you/your account, so please don’t poke us on IRC or elsewhere about it.)

This is all obviously intended to be temporary, just until we’re able to get the process fully automated again. If you have any Ruby experience/know-how and would like to help out, please check out OTHER-248 (and possibly OTHER-254). There’s also MBS-8836 on the MusicBrainz server side for the Perl-istas.

Let us know if you have any concerns or questions about this (reminder: temporary) approach, either in the comments or on the forums. I personally hope it’ll work well enough to carry us through for a while longer until everything is ready.

GSoC 2016 students and projects

Google announced the final list of Google Summer of Code 2016 students and their projects yesterday. The list of MetaBrainz’ projects can be seen at our page on the GSoC site, but just for good measure, here’s the rundown:

MusicBrainz
Jeff Weeks (weeksio) returns to finish up the SOLR search server. We’re really hoping that this will be the end of our current search server woes. He will be mentored by the German duo of Ulrich Klauer (chirlu) and Rob Kaye (ruaok).
MusicBrainz Picard
Rahul Raturi (rahulr) will be working on improving searching MusicBrainz from within Picard, mentored by MusicBrainz’ senior developer Michael Wiencek (bitmap).
BookBrainz
Max Prettyjohns (QuoraUK) is going to try and take on adding gamification to our fledgling book/literature database. He will be supervised by the BookBrainz project leads and lead developers Ben Ockmore (LordSputnik) and Sean Burke (Leftmost).
ListenBrainz
Pinkesh Badjatiya (armalcolite) has pledged to tackle adding a much requested feature for our youngest project: implementing a Last.FM compatible submission API. Robert Kaye (ruaok) will be the one guiding him along.
AcousticBrainz
Daniele Scarano (hellska) will be spending the summer writing a toolkit for creating datasets, which should help researchers using AcousticBrainz. He will be mentored by MetaBrainz software engineer Roman Tsukanov (Gentlecat).
Kartik Gupta (kartikgupta0909) has set out to create an offline client for computing AcousticBrainz dataset evaluations. Alastair Porter (alastairp), the AcousticBrainz project lead, will be their mentor.
Goran Cetusic (cetko), our final student of this year, will be exploring how AcousticBrainz data can be utilised within Google’s BigQuery storage under the guidance of Alastair Porter.

Congratulations and good luck to all our students! We’re looking forwards to following your progress over the summer and see what you end up with. 🙂

For all the students that applied but did not get accepted: we appreciate your applications, and even if you did not make the cut this year, we hope that you will stick around and apply with us again next year when we know you better – and you know us better.

For now, let the community bonding… begin! 🙌

Announcing python-musicbrainzngs, release 0.6

From the better late than never department…

After more than 2 years we’ve finally released version 0.6 of python-musicbrainzngs, a library for accessing the Musicbrainz webservice from python.

After such a long time we have perhaps too many new changes to describe. Some major changes include:

  • Better handling of authentication private user collections
  • Support for loading all types of user collections (artist, event, place, recording, release, work)
  • Work attributes
  • Support for the Cover Art Archive
  • Support for Events, Instruments, Places, and Series

And numerous other bug fixes and small changes. See the CHANGES file  for more information.

This release contains contributions by Alastair Porter, Corey Farwell, Ian McEwen, Jérémie Detrey, Johannes Dewender, Pavan Chander, Rui Gonçalves, Ryan Helinski, Shadab Zafar, and Wieland Hoffmann. Thank you everyone!


The new version can be downloaded from github, pypi, or installed with pip

  • https://github.com/alastair/python-musicbrainzngs/releases/tag/v0.6
  • https://pypi.python.org/pypi/musicbrainzngs
  • pip install musicbrainzngs

Server update, 2016-04-04

This is a small bug-fix release while we work on finishing the May schema change update. Thanks go to reosarevok and ethus3h for their patches this time around. The git tag is v-2016-04-04 and you can find the complete changelog below.

Bug

  • [MBS-8850] – No events tab for tags
  • [MBS-8861] – Vertical spacing off on editor profile if “last login” is missing (account admins only)
  • [MBS-8874] – Editing an entity sometimes shows it as a possible duplicate of itself
  • [MBS-8886] – Header menus should work without JavaScript

Improvement

  • [MBS-8591] – Increase pagination item count

Deprecating MBIDs

This post is an April Fools joke. Rest assured, we have no intention of changing the MBID system that MusicBrainz currently uses.

But, like all good parody news items, there is an element of truth behind this post. The announcement of the Echo Nest API shutdown is real, and with this change you will no longer be able to use the Echo Nest IDs to look up information. This particularly hurts users of the Million Song Dataset, which maps each track to the Echo Nest ID. The new Spotify API isn’t even providing any compatibility api or ID mapping, leaving users to look up 1 million Spotify IDs in the remaining months that the the old Echo Nest api will remain available.

At MusicBrainz, we understand the importance of a stable identifier system. That’s why, 16 years ago, we picked these unwieldy-looking UUID identifiers – that have since proven to have stood the test of time, with room to continue growing. You can look up an MBID made 16 years ago, today – and it will still work another 16 years in the future.

Hello all,

Following Echo Nest’s bold announcement that Echo Nest ids are being replaced by Spotify IDs, we figured it was time to make our own ID change public as well – MBIDs were a fantastic idea 16 years ago, but let’s face it, they’re not the most beautiful thing around, so our MBIDs will now also be replaced by Spotify IDs to help with a proper mapping across tools. Anything without a Spotify mapping will simply get purged. This should greatly simplify the data we have and remove any doubt for some releases whether they exist or not – if they’re on Spotify, they clearly exist!

We would like to commend Echo Nest on their brave leadership in this, giving us the courage to move on from our ancient heritage and try new things. With the speed technologies evolve in this digital age, it can be hard to keep up with things and keep things fresh, but Echo Nest is showing the way forward, and we’re delighted to be able to follow so quickly in their path.

I hope you all will welcome this bold move by our team. We hope to have it ready by next schema change. We know we’re excited! 😀

PS. No, we will not provide a mapping between MBIDs and the new Spotify IDs. We trust our data users to be capable to set things up on their own. Happy hacking! 🙂

Server update, 2016-03-21

The most noticeable change in this release is that we’re using Wikidata links to fetch images for any entity that has them. Thanks to Roman Tsukanov for working on this cool new feature! We’ve also made the header menus require clicks to open and close, and fixed several bugs listed below. The git tag is v-2016-03-21.

Bug

  • [MBS-7914] – alias list not included in track level artist credits when fetching release information
  • [MBS-8837] – Event edits fail to apply with ERROR: invalid input syntax for type time: “1970-01-01T19:00:00”
  • [MBS-8848] – Own private collections ignored on entity pages
  • [MBS-8858] – Edit medium edit stuck trying to use a deleted recording
  • [MBS-8862] – Search edits: release group condition is broken

Improvement

  • [MBS-6381] – Use Wikidata URLs to fetch images for entities
  • [MBS-8843] – Require clicking on the header menus to open them

New Feature

  • [MBS-6152] – Provide a better way to list private collections in /ws/2/release output

Task

  • [MBS-8805] – Drop the completely unused pre-NGS tables on totoro

6 degrees of Vince Gill

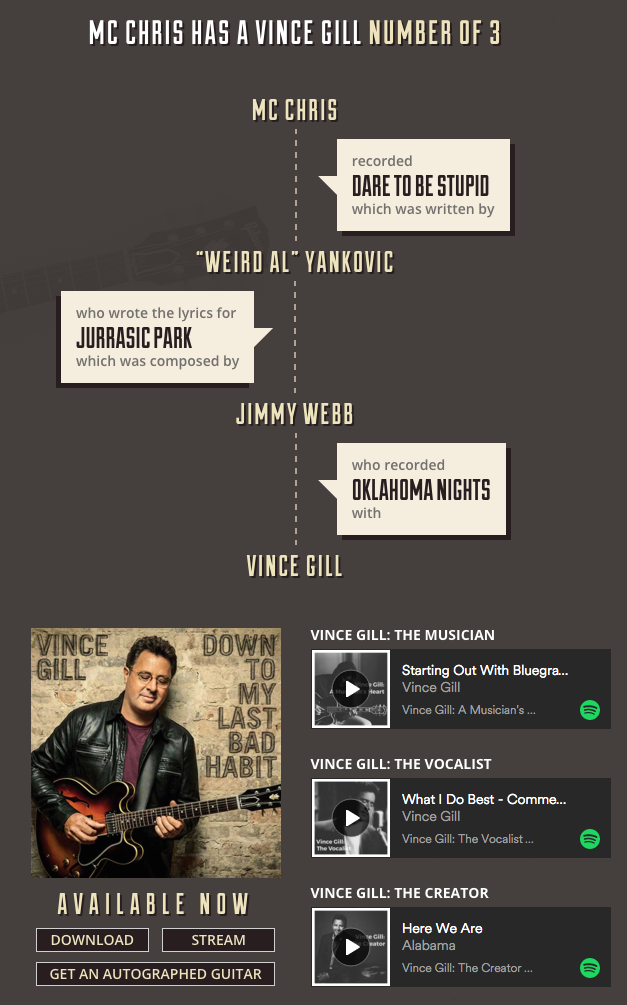
I’m not sure that we’ve talked about this cool project yet, so I’ll catch up on that now. The new site Six Degrees of Vince Gill allows you to enter an artist name and see how many degrees of separation there are between your artist and Vince Gill. This project comes from Universal Music’ Nashville group — I’m happy to see our data get used in interesting ways like this!

Now, if you want to see someone relate to Vince Gill in seven degrees, have a look at how I relate to him. 🙂

Screen Shot 2016-03-16 at 17.45.29.


May 2016 schema change release details

In about two months time we’ll have the next schema change release: May 16, 2016. Even after skipping the fall schema change release, this release is going to have few changes that will impact our downstream users. Most of the tickets in this release will make minor improvements to database indexes and edit tables. If you are one of the few users of our edit data, then you should delve deeper into the list of tickets in this release. For everyone else, I will summarize the tickets with a greater impact.

In a previous blog post we also talked about upgrading the minimum required version of postgres. We received no real feedback requesting for us to upgrade to 9.4, but we did receive some feedback that some people would prefer 9.5, which is our preference as well. Based on that feedback, we’re going to make PostgreSQL version 9.5 the minimum required version. If you’d like to run a MusicBrainz replicated instance via our Live Data Feed, you will need to run Postgres 9.5!

The official minimum supported Ubuntu release as of now is still Ubuntu 10.04 LTS (Lucid Lynx) which reached end-of-life a year ago. We will upgrade that to Ubuntu 14.04 LTS (Trusty Tahr) at the schema change release. In particular, this means that we might start using Perl 5.18 features in the MusicBrainz Server code (as opposed to Perl 5.10 currently).

We understand that this is potentially a lot of work for some of our users, but occasionally we need to upgrade our requirements. We try and limit these sorts of upgrades as much as possible, so please bear with us.

Finally onward to the details of the release. Please take a look at the list of issues that will be addressed in this release. The few tickets worth discussing in details are:

  • MBS-8838 – “Add gids to all *_type tables“. This ticket adds MBIDs (GIDs in schema lingo) to all of our tables that define a type for some database element. Given that we recommend that external users never reference our data by row ids, we really need to provide proper permanent MBIDs to all elements of our database.
  • MBS-6024 – “Support more than one barcode on same release (SQL edition)“. This ticket adds the ability for the database to contain more than one barcode for a given release. However, this ticket does not include the user interface portions of this feature. The team will add the user interface/edit portions of this feature in a later, non schema change release.
  • MBS-4501 – “Alternative tracklists“. This ticket creates a new feature that would allow an alternative tracklist to be used for a given release. This is a better solution for handling conflicts between our style guidelines and how the data appears on the release. It is also a more elegant solution for translations of releases into different languages.

As usual, we will post final details about the release shortly before the release happens. If you have any questions about this release, feel free to ask specific questions in the tickets or general questions in the comments below.

(Edited 2016-03-16 at 12:55 UTC to add the upgraded Ubuntu requirement.)