URLs to MusicBrainz Server Virtual Machines were changed in the process, you may find them at ftp://vm.musicbrainz.org/pub/musicbrainz-vm/, documentation was updated to reflect this change.
On September 29th, we received an email from a company called Web Sheriff, urgently requesting us to remove the name Adetayo Ayowale Onile-Ere from the Taio Cruz artist page. We investigated this request and quickly found that there were other resources on the net referencing both names. We also found other evidence of Web Sheriff working to change the name of this artist in other venues/sites.
One of the cornerstone’s of our music database, and our principles, is to keep the data as clean and accurate as possible. We aim to edit with due diligence.
We declined to make the change, and made the following request: If you can provide us with a birth certificate that shows Taio Cruz as the birth name, we’d be happy to make the change. Web Sheriff agreed to do that and on October 13th we received a copy of this document:
I inspected the document and quickly felt something was amiss. The document purports to be a Birth Certificate from the Chelsea and Westminster Hospital in London, UK and the father’s occupation is listed as “Lawyer”. While I am not a legal expert, my understanding is that the term for someone who practices law in the UK is not lawyer, but rather attorney, barrister, or solicitor. The use of “Lawyer” in this context seemed strange to me.
With this observation as my motivation, I rang up Her Majesty’s government to ask how I would go about verifying the validity of a birth certificate. I was told that the UK government could not verify the authenticity of a certificate, but that I could request a copy of the certificate myself since they are public record. For a fee of 9 pounds 25p and two weeks time I would receive a copy of the certificate in email. I thought that was a good way forward and I asked to order a copy. The lovely lady who helped me, painstakingly endeavoured to ensure that all the details related to my request were communicated correctly. I have no doubts that I relayed the data I had accurately.
And with that, I waited. On November 8th, I received mail from Her Majesty’s government informing me that no such birth certificate could be found and that my payment will soon be refunded.
This strongly suggests that the document provided to us by Web Sheriff was not a legitimate copy of a birth certificate for Jacob Taio Cruz.
Being coerced to make changes to facts in our database based on false pretences – I find such things despicable. We felt harassed and intimidated by the efforts of Web Sheriff, pressuring us to make this change.
I hope that this blog post will remind others to be wary and vigilant, and not give in easily to coercion. This is what I intend to do with Web Sheriff, and others, going forward and I hope you will do the same!
UPDATE (March 9, 2016): This post has been edited for clarity. These changes follow a specific request from Web Sheriff that we delete or amend the post:
we must insist that you withdraw your false allegation of forgery
UPDATE: Since posting this, sharp readers spotted more problems with the certificate:
There is no “county of Westminster”. There is a city of Westminster.
This release fixes the web service to support all the new entity types that can be added to collections since the last release, including to support submission, and introduces a few new browse requests (browsing collections by entity gid or editor name; browsing entities by collection gid). These are documented at https://musicbrainz.org/doc/Development/XML_Web_Service/Version_2.
Area pages now have a “Users” tab where you can see other editors from that area, provided they’ve filled out that info in their profile.
A “single sign-on” endpoint has been added for logging into our new community forum, to replace the previous OAuth2 method. The main benefit over OAuth2 is that it now keeps peoples’ usernames and email addresses in sync with their MusicBrainz account.
Thanks to Roman Tsukanov (Gentlecat) and Frederik “Freso” S. Olesen for their work on today’s release. The git tag is v-2016-03-07 and the complete changelog is below.
Bug
[MBS-3125] – collection queries via the webservice are broken
[MBS-5323] – GET request for releases in a collection returns unordered results
[MBS-8459] – WS doesn’t have work collection endpoints
It’s been over a year since we last posted about AcousticBrainz, but a lot of work has been going on in the background. This post will give an overview about some of the things that we’ve achieved in the last year.
Data contributions
Our last blog post was neatly titled “What do 650,000 audio files look like, anyway?” Back then, we thought that this was a lot of submissions. Little did we know… I’m glad to report that we now have over 3.5 million submissions, of which almost 2 million are for unique MBIDs. This is a great contribution and we’d like to thank everyone who submitted data to us.
Dataset and model building
MusicBrainz coder Gentlecat returned to participate in Google Summer of Code last year and developed a new tool to let us create datasets and create new computational models. We’re really excited about how this can allow community members to help us increase the quality of the semantic information we provide in AcousticBrainz. We will make another blog post soon explaining how it works.
We presented an academic overview of AcousticBrainz (PDF) at the 16th International Society for Music Information Retrieval (ISMIR) conference in Malaga, Spain. The feedback from the academic community was very encouraging. Many people were interested in the data and wanted to know what they could do with it. We hope that there will be some new projects announced using the data at this year’s conference.
Integration with other data sources
MusicBrainz and AcousticBrainz don’t exist in a vacuum. One important thing that we need to make sure we do is interact with other researchers and products in the same field. To that end, we started AcousticBrainz Labs, a showcase of some of the experiments that we’re working on in AcousticBrainz. The first thing we have published is a mapping between AcousticBrainz and the Million Song Dataset, that we hope people will use to compare these two datasets.
Database upgrades and Data format changes
We’ve just upgraded to PostgreSQL 9.5 (from 9.3), which allows us to use the new jsonb datatype introduced in PostgreSQL 9.4. This change lets us store feature data more efficiently. We also made some changes to the database schema to let us start creating new data from datasets and computation models.
One result of this is that we are creating a new complete data dump, and stopping the old incremental dumps. We are also taking the opportunity to automate this incremental dump process, which is something that a number of people have asked for.
Another change is that the format of the high level JSON data is changing. This is to better reflect some of the complexities that exist in hosting such a large and varied dataset.
Contribute to AcousticBrainz development
We’re always interested in help from other people to contribute data, code, and ideas to AcousticBrainz. Once again, MetaBrainz is participating in Google’s Summer of Code, and AcousticBrainz is a possible project to work on. If you’re not a student you’re still welcome to work with us.
Hello all members of the *Brainz community, I have got something in store just for you!
Some people may have noted talks and whispers about a grand and glorious move to use Discourse for various discussions related to MusicBrainz and all other MetaBrainz projects. The intention of it is to replace and unify both the now-dead mailing lists (R.I.P.) and our current forums. Guess what? The day has come at last!
The MetaBrainz Community Discourse can be found at https://community.metabrainz.org/ and is our new home for all discussions about MusicBrainz, BookBrainz, AcousticBrainz, and whatever other kind of *Brainz you want to talk about.
One of its major features is that it does not require yet another user (like the current forums, our ticket tracker, the wiki, …). When you press “Sign Up” or “Log In” it will ask you to authenticate with MusicBrainz to access some basic information. Once given permission, it will direct you back to the Discourse site and you’re logged in. (You can revoke the permission at a later point, should you need to.) No more having a dozen username/password combinations, just to participate in the community!
The site does still have some rough edges though, and various things are likely to get tweaked over the coming weeks, but today being the 1st day of (N. hemisphere) spring, I thought we should enjoy this season of “rebirth, rejuvenation, renewal, resurrection and regrowth” with this new baby of the MetaBrainz community.
A couple of people have already gone and started some discussions there, but feel free to go there yourself and start your own discussion. If you have started a discussion on the current/old forums, now is also a good time to restart/continue/move that discussion to the Discourse site as the forums will be put into read-only mode any day (posts will not be moved over).
If you don’t know where to start, start with reading the FAQ and after that, you could post to the introduction thread and introduce yourself. To get an overview about what’s going on, https://community.metabrainz.org/categories has a list of the categories currently in use and https://community.metabrainz.org/tags has a list of the tags in use. You could also just go to the front page, https://community.metabrainz.org/, and see what discussions are active right now and join in there. 🙂
I hope to see a lot of lively and friendly and constructive discussion going on there, so head over there and start making it happen. 😉
Your friendly neighbourhood community manager,
Freso
If you’re a prospective GSoC student who is hoping to apply with MetaBrainz this year, be sure to check out our guide to getting started and our currently suggested projects – but also note that we’d love for you to come up with your own suggestion! You may also want to take a look at the application template, which contains suggestions about
some of the things you should do and know before submitting your proposal.
For those of you who are already members of our community, you’re also welcome to add ideas to the suggestions page, and please be gentle when the GSoC hopefuls come along. 🙂
That’s really all for now, but expect to hear more about GSoC and our participation over the coming months!
The style of the website has changed to use our new logo and better match the rest of the *Brainz family. It may be rough around the edges in some areas, but we’ll continue to make improvements as we receive feedback. Thanks to Roman Tsukanov (Gentlecat) who did all of the initial work on this.
Other Changes
Nicolás Tamargo (reosarevok) has fixed our header menus to be clickable on touch devices, and we have some other fixes and improvements from Ulrich Klauer (chirlu) and myself listed below. The git tag for today’s release is v-2016-02-22.
Bug
[MBS-8007] – Can’t change collection type of existing collection
[MBS-8624] – Components for server-side rendering are not equivalent to TT macros
[MBS-8771] – Contact-URL on start page result in “Page Not Found”
[MBS-8772] – Big Audio Dynamite is high-lighted, but no open edits seem around
[MBS-8776] – JSON-formatted collection release list shows page total and not overall collection total
[MBS-8789] – “{user} has not tagged anything” in user/tags seems broken
[MBS-8801] – “A group of artists cannot have a gender” when removing the gender
Improvement
[MBS-739] – Menu items with dropdowns should not have actions under them (other than the drop down opening)
[MBS-6212] – No link to edit profile on the profile
The Google Code-in is pretty much over for this time, and we’ve had a blast in our first year with the competition in MetaBrainz with a total of 116 students completing tasks. In the end we had to pick five finalists from these, and two of these as our grand prize winners getting a trip to the Googleplex in June. It was a really, really tough decision, as we have had an amazing roster of students for our first year. In the end we picked Ohm Patel (US) and Caroline Gschwend (US) as our grand prize winners, closely followed by Stanisław Szcześniak (Poland), Divya Prakash Mittal (India), and Nurul Ariessa Norramli (Malaysia). Congratulations and thank you to all of you, as well as all our other students! We’ve been very excited to work with you and look forwards to seeing you again before, during, and after coming Google Code-ins as well! 🙂
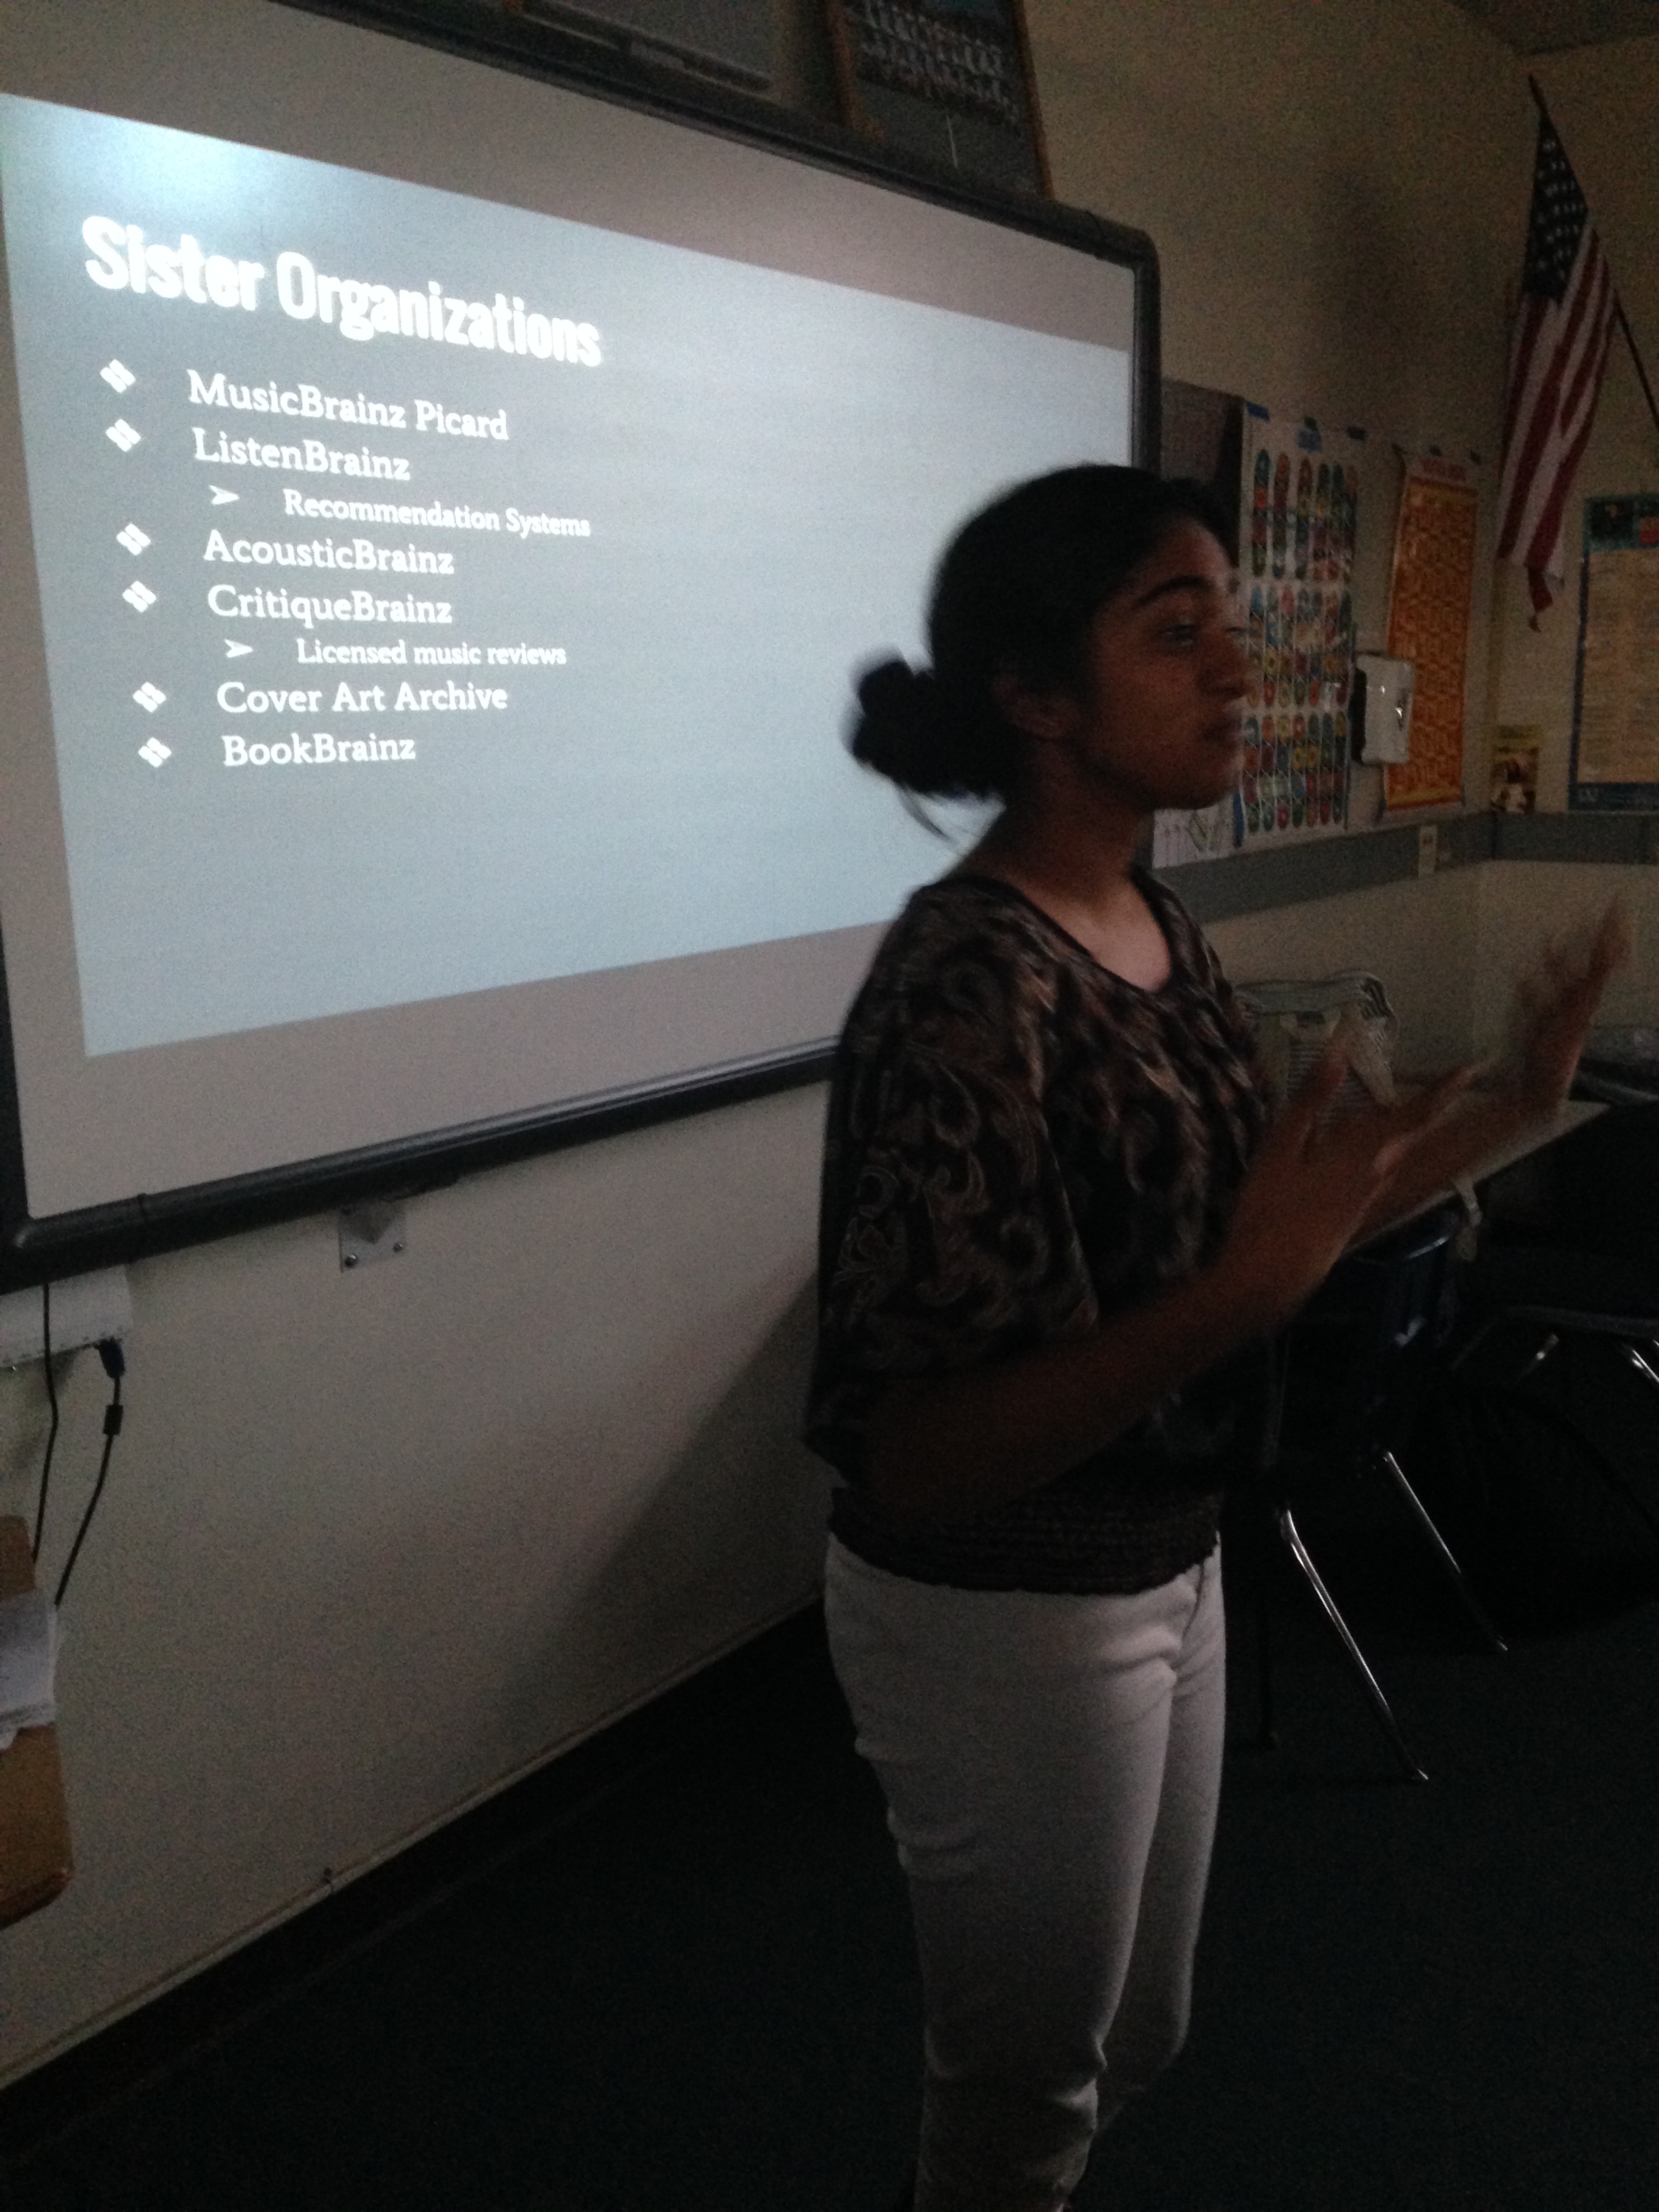
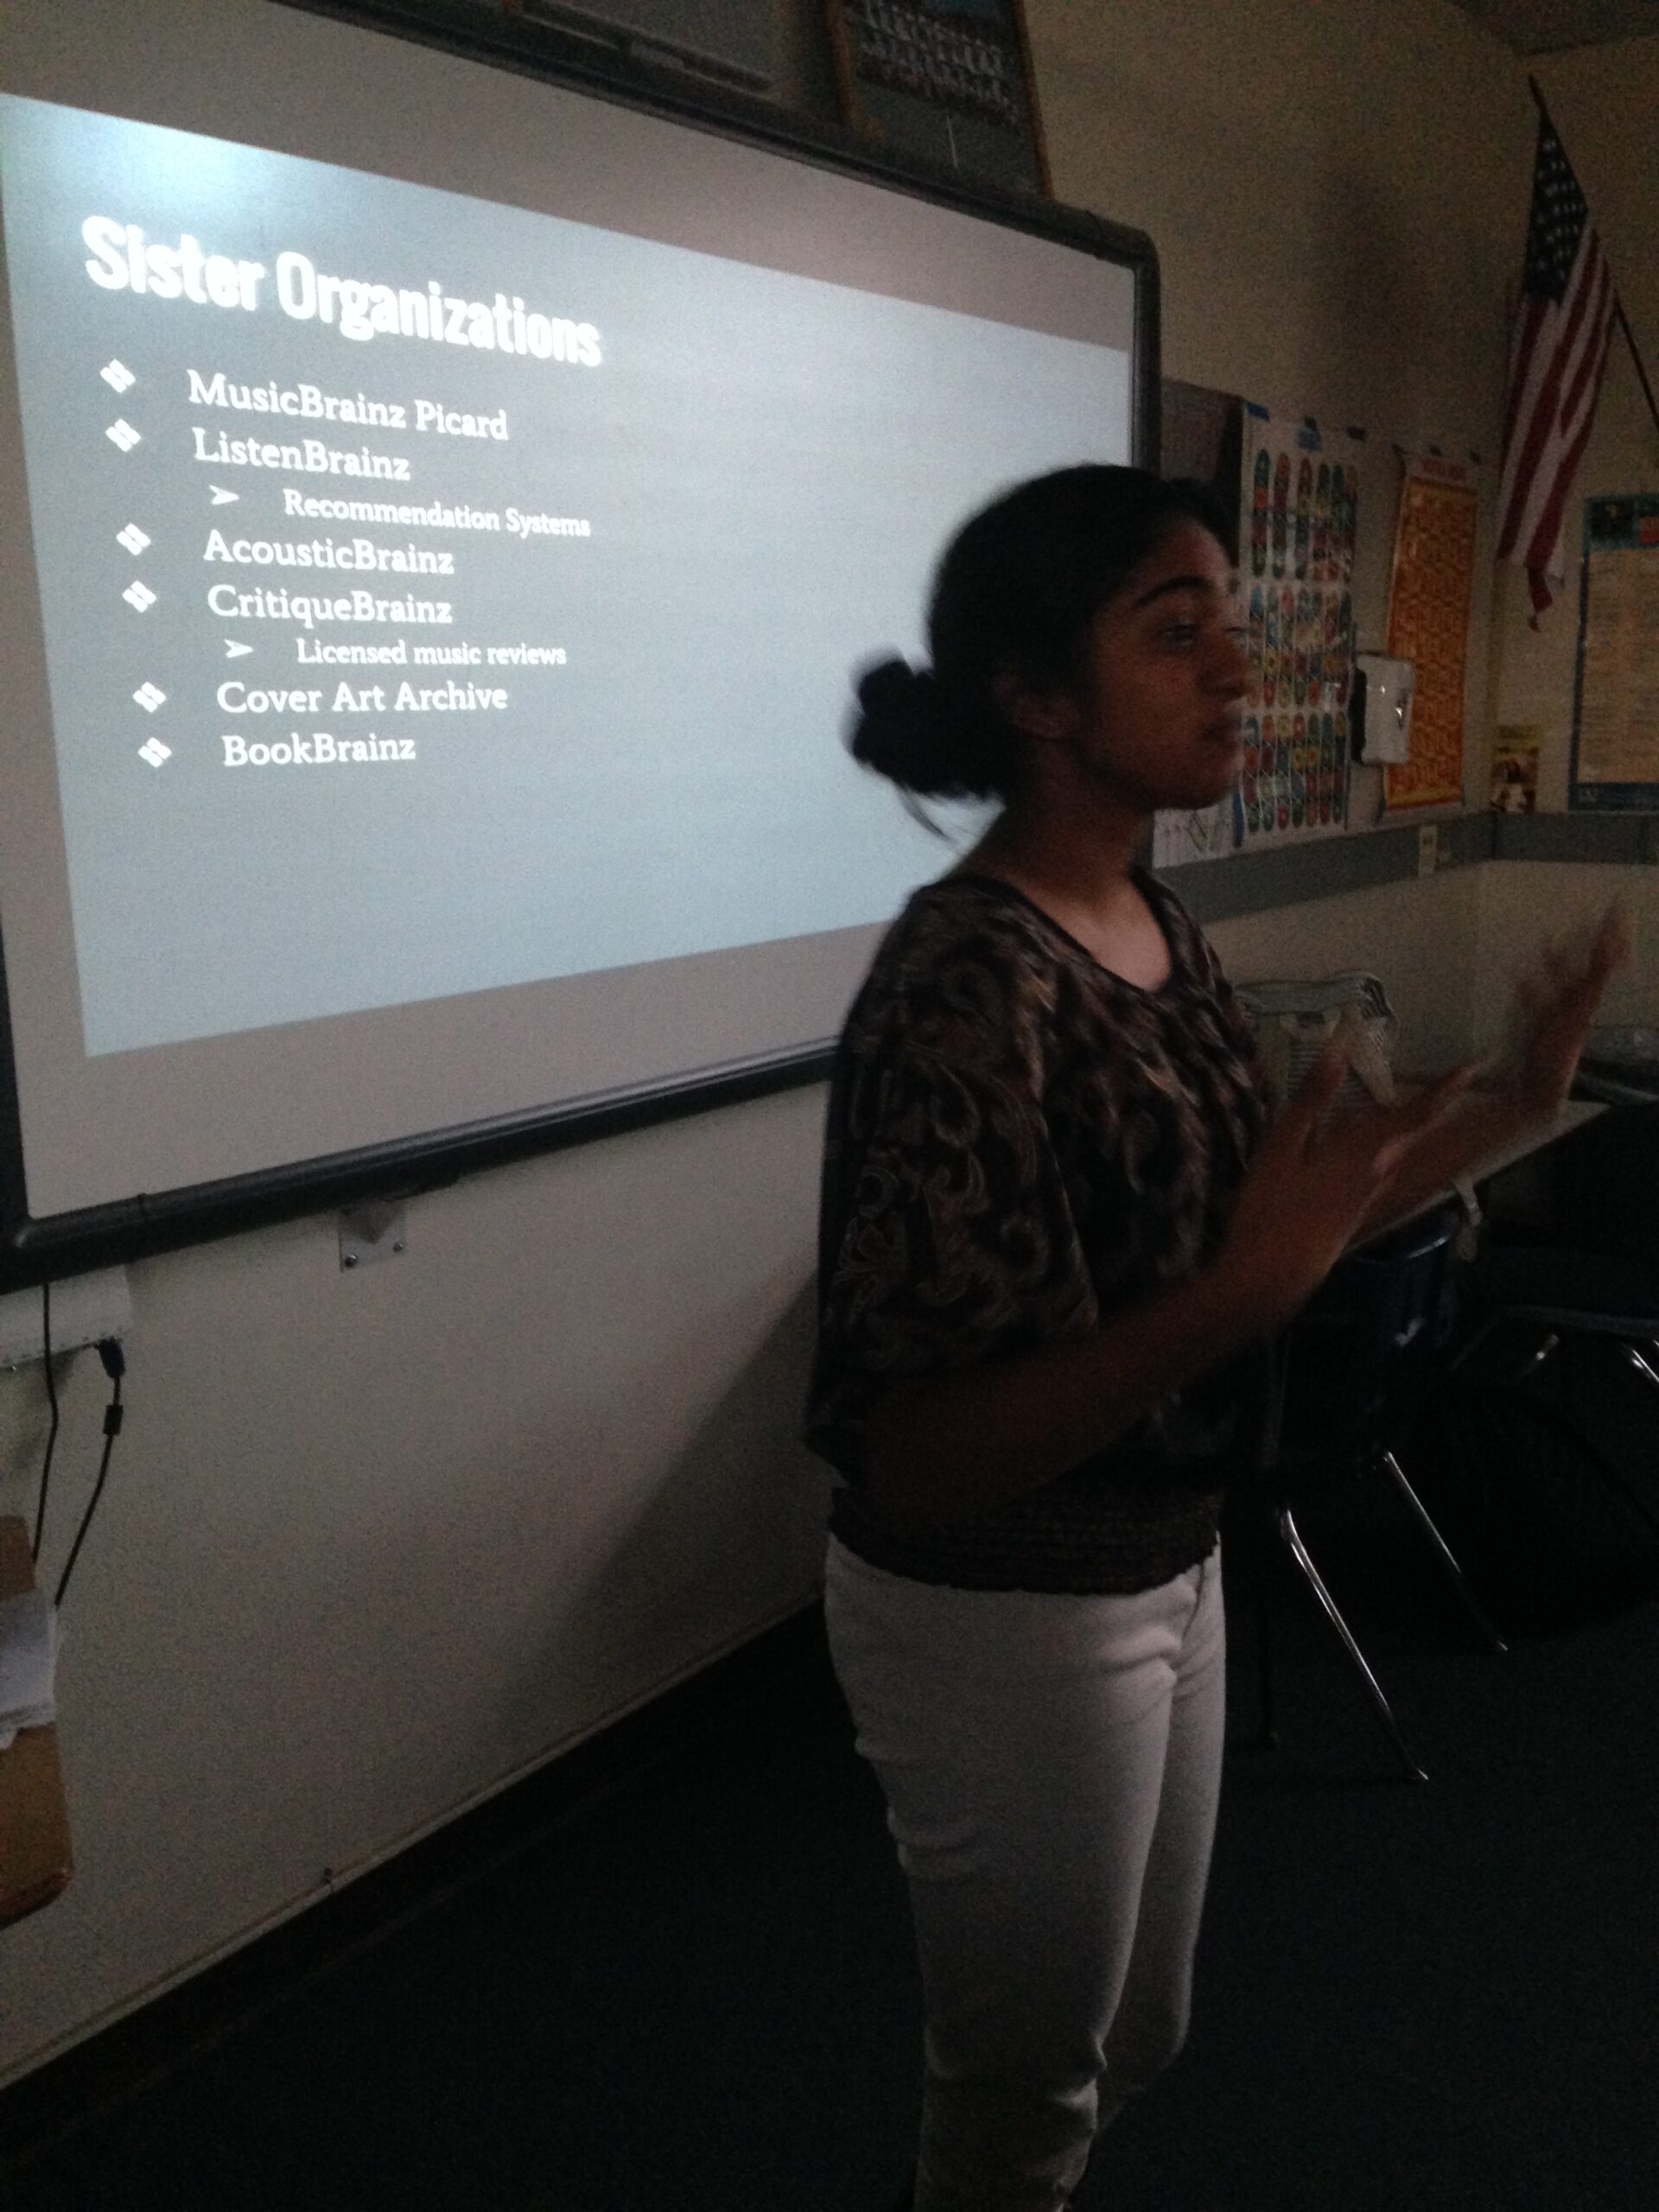
Indian student Rayne presenting MusicBrainz to her classmates.
In all we had 275 tasks completed during the Google Code-in. These tasks were divided among the various MetaBrainz projects as well as a few for beets. We ended up having 29 tasks done for BookBrainz, 124(!) tasks for CritiqueBrainz, 95 tasks for MusicBrainz, 1 task for Cover Art Archive, 6 tasks for MusicBrainz Picard, 3 tasks for beets, and 17 generic or MetaBrainz related tasks.
Some examples of the tasks that were done include:
A couple of YouTube introduction/tutorial videos. There are a couple more we didn’t make available yet, but a huge thanks to Caroline and JefftheBest for creating these!
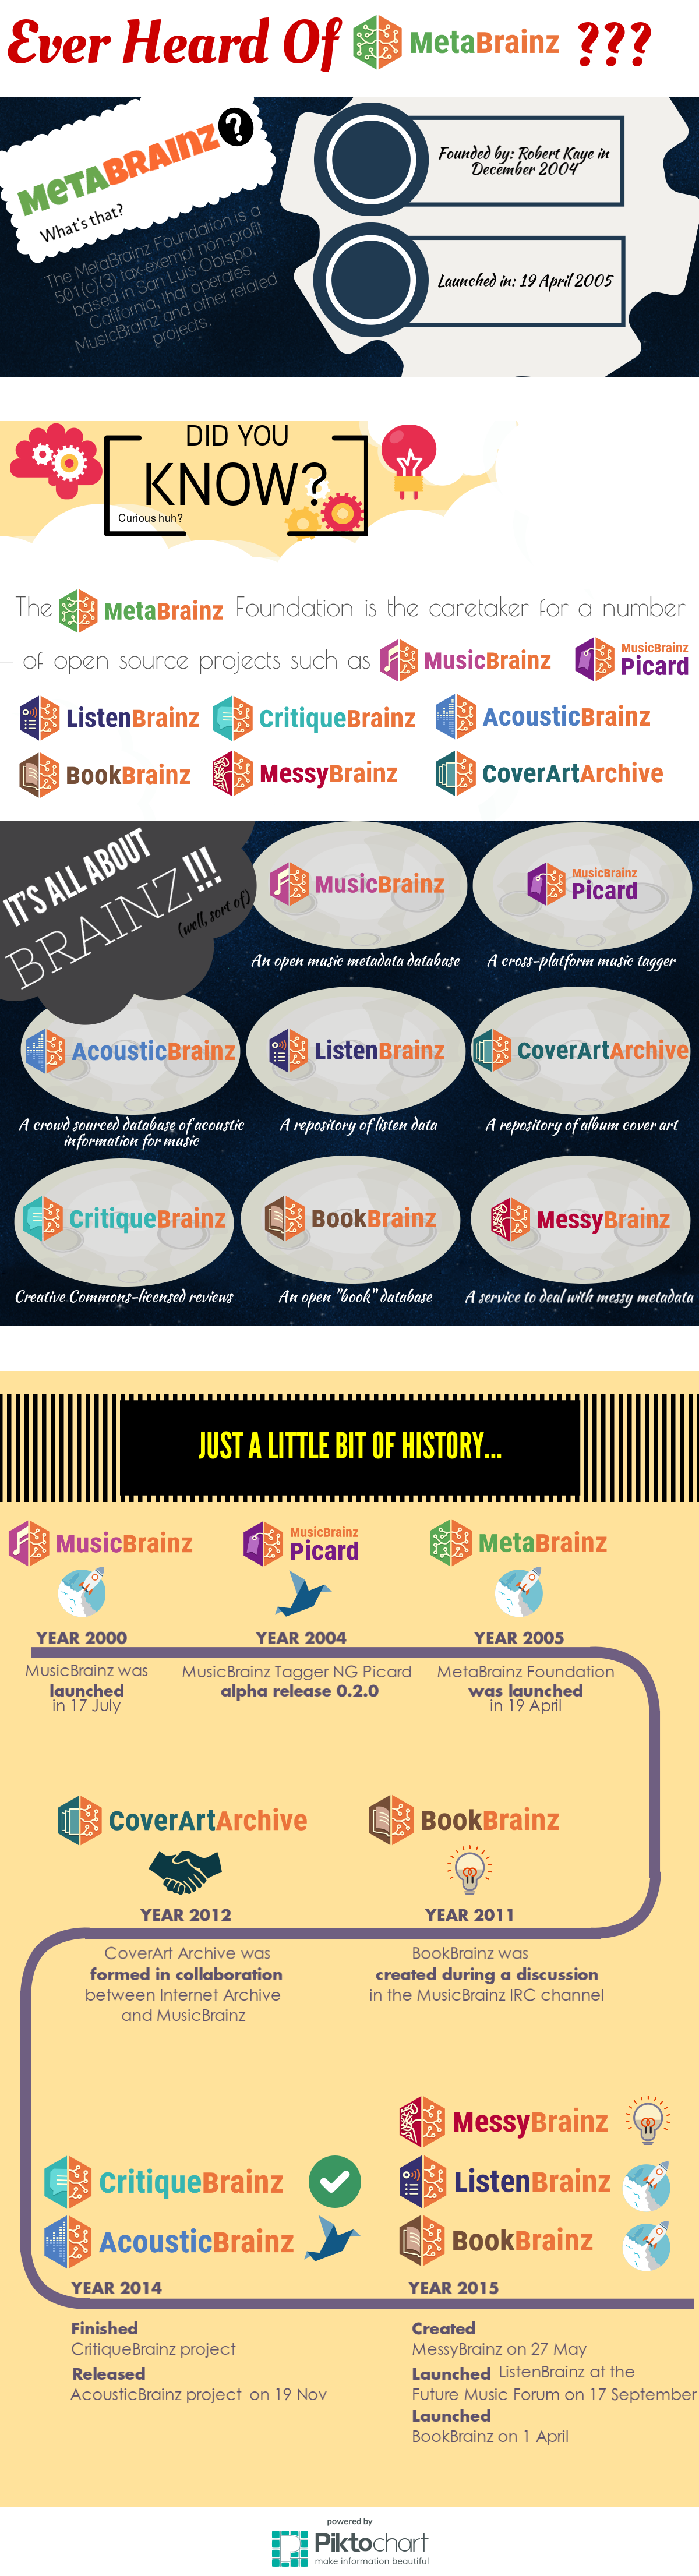
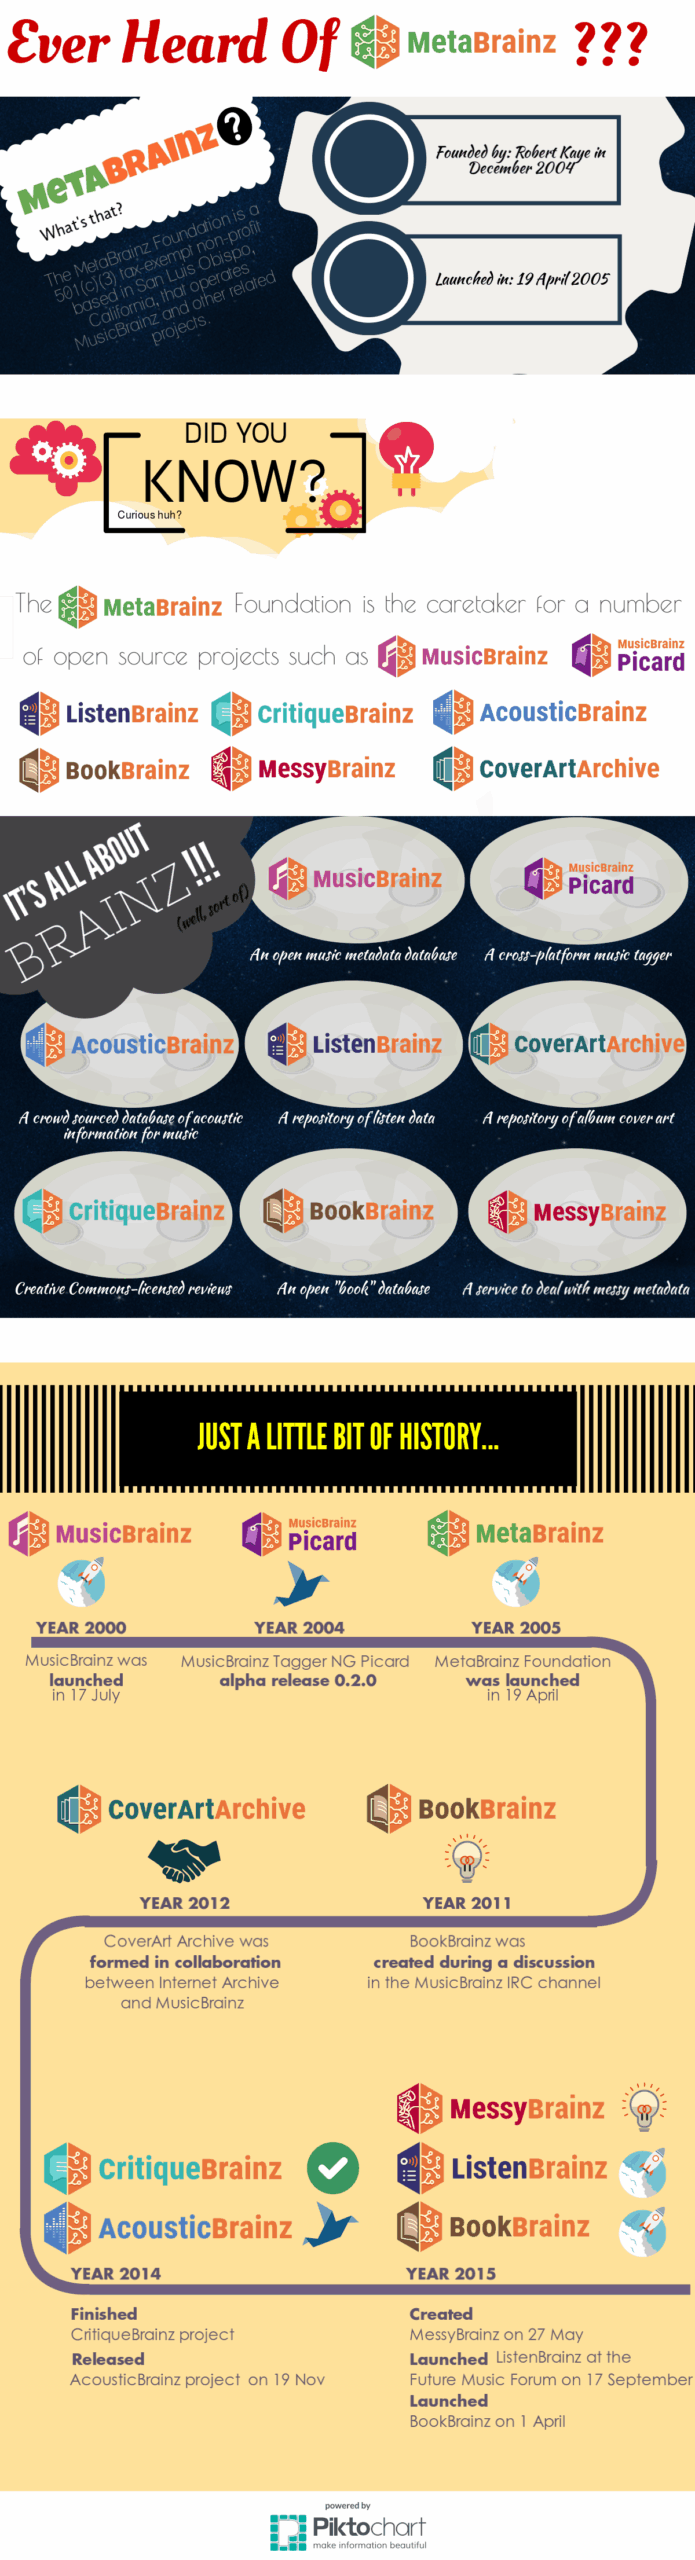
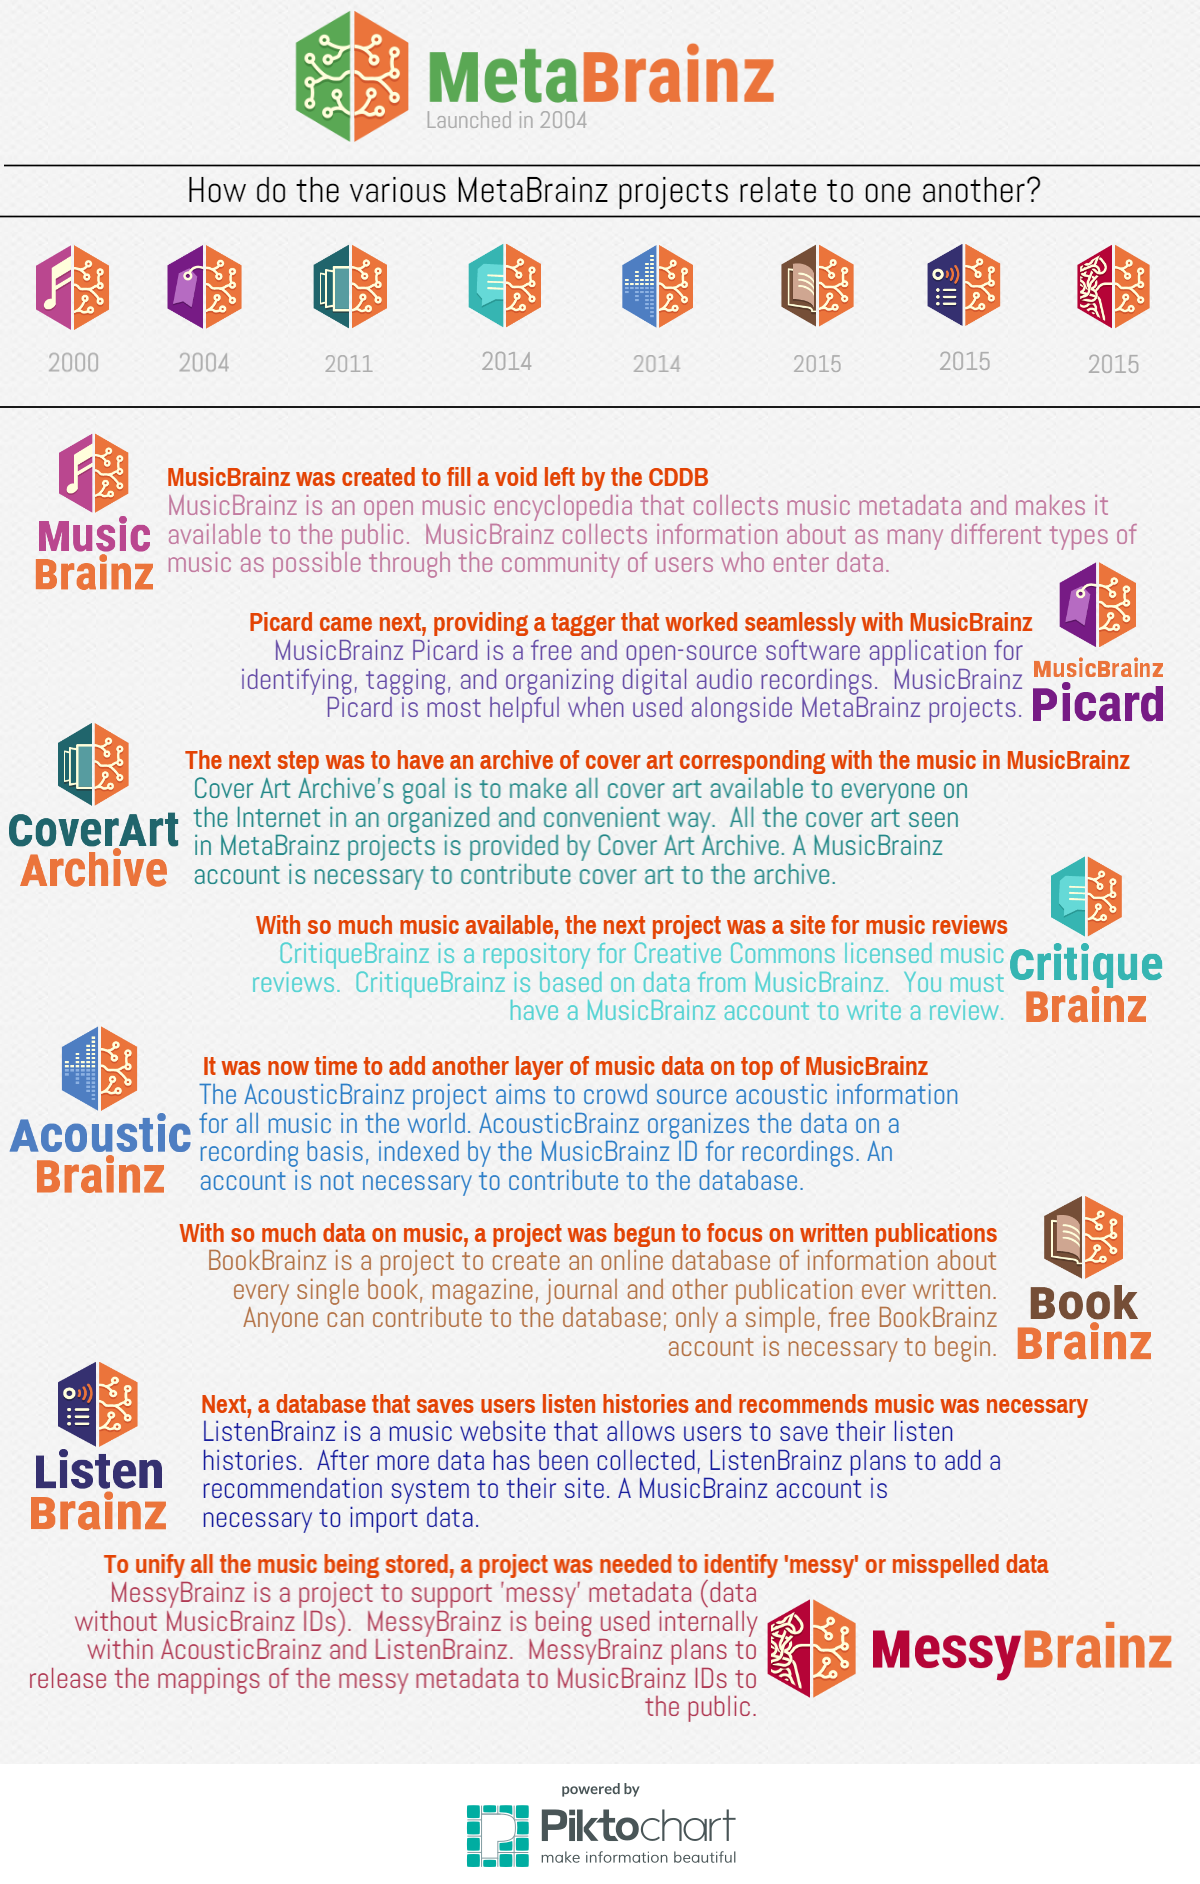
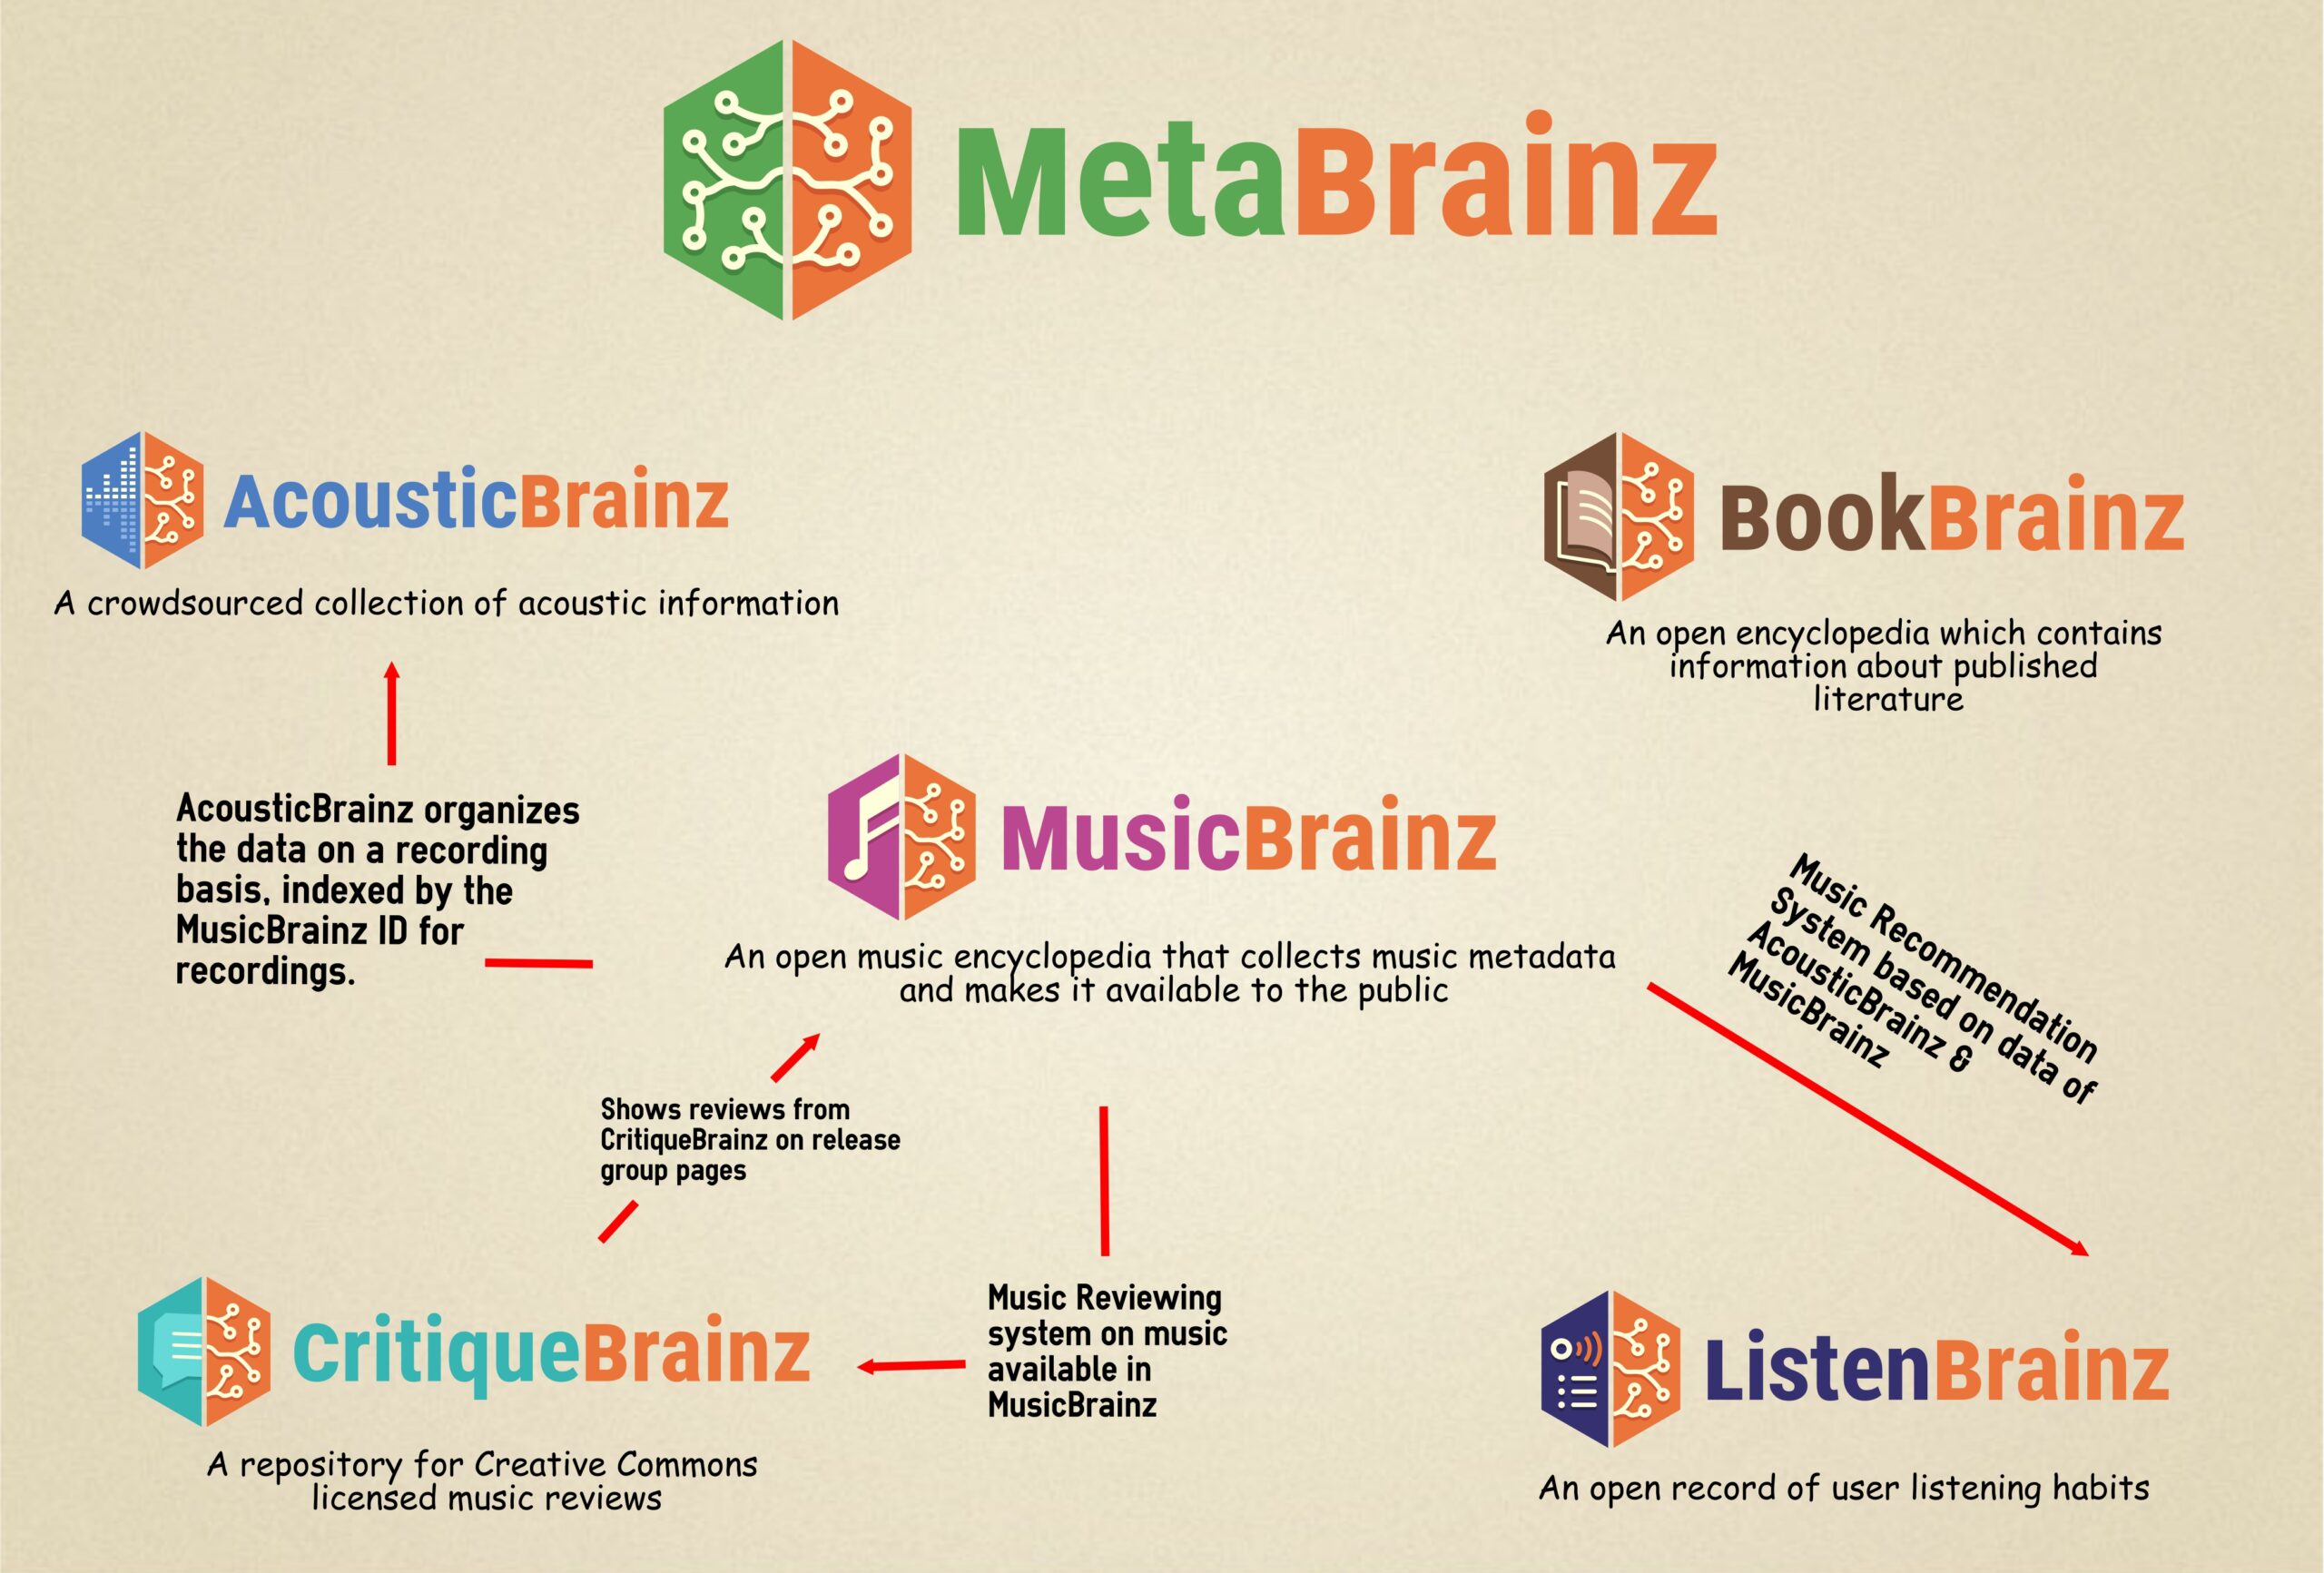
3 infographics were made to describe how the MetaBrainz projects relate to each other (see gallery below)
7 classroom presentations were held, spreading the word about open source, MetaBrainz, and MusicBrainz to young students around the world (pictures from a few of these in the gallery below)
In all, I’m really darn happy with the outcome of this Google Code-in and how some of our finalists continue to be active on IRC and help out. Stanisław is continuing work on BookBrainz, including having started writing a Python library for BB’s API/web service, and Caroline is currently working on a new icon set for the MusicBrainz.org redesign that can currently be seen at beta.MusicBrainz.org.
Again, congratulations to our winners and finalists, and THANK YOU! to all of the students having worked on tasks for MetaBrainz. It’s really been an amazing ride and we’re definitely looking forward to our next foray into Google Code-in!
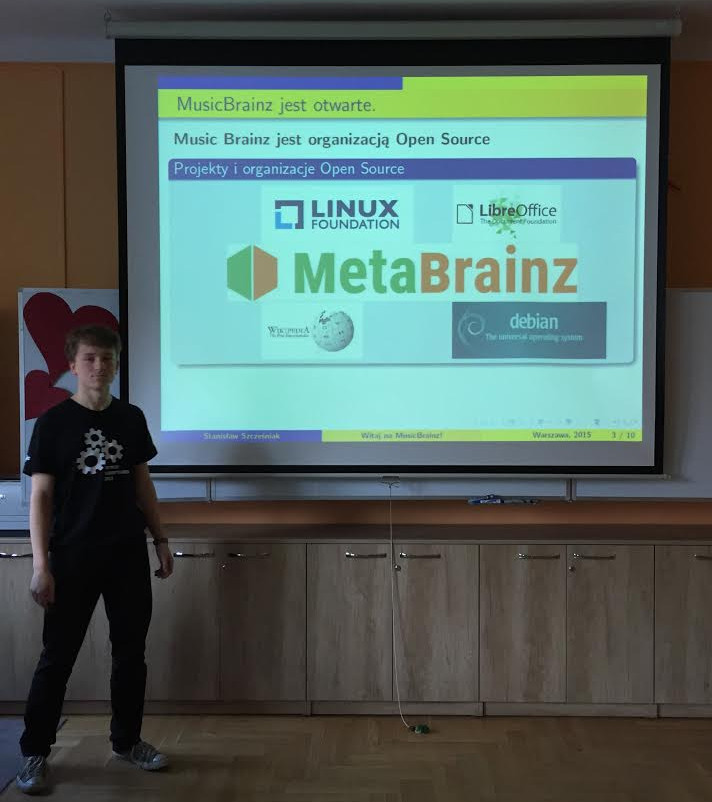
Polish student Stanisław Szcześniak presenting about MusicBrainz.
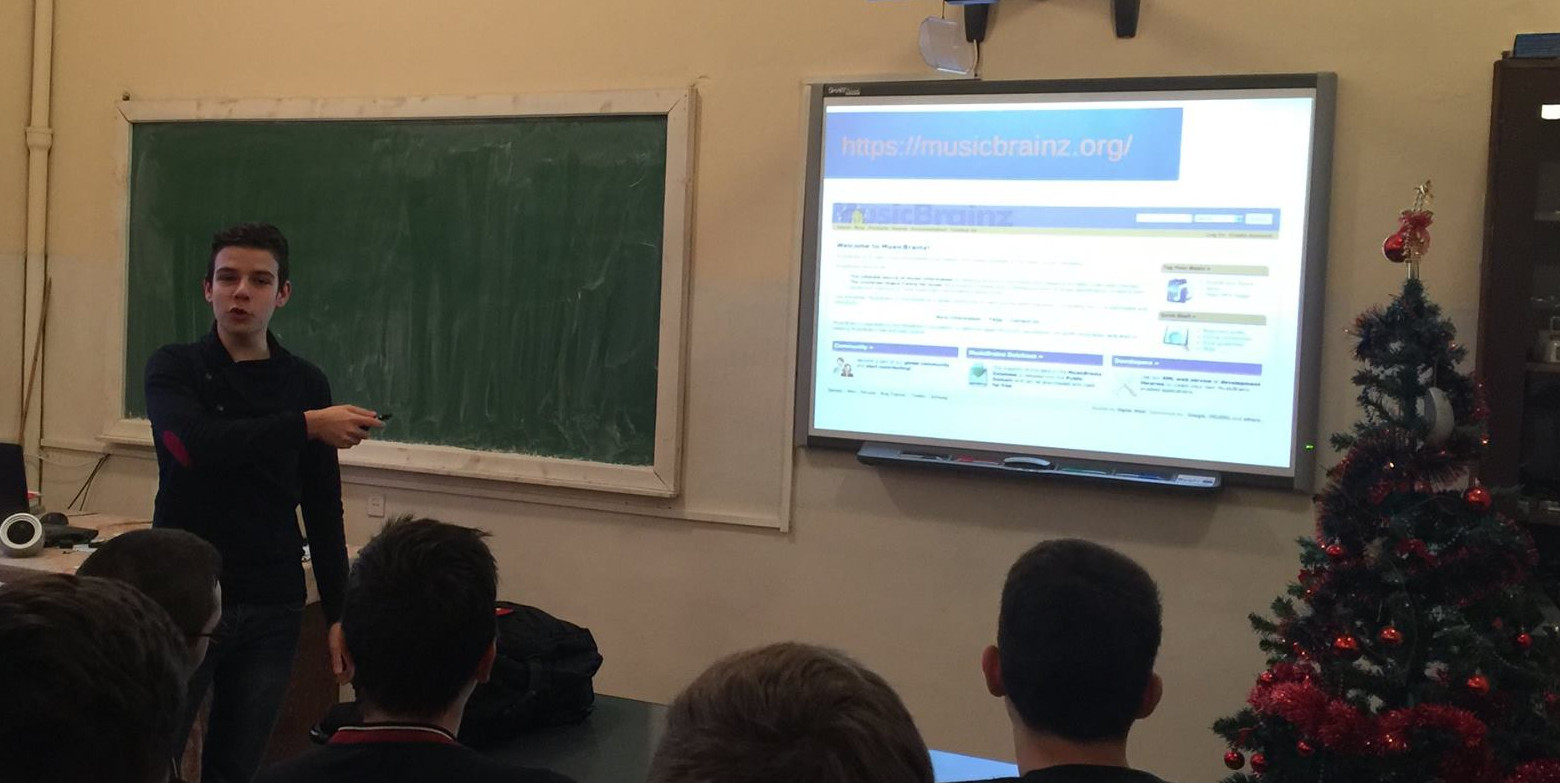
Romanian student Borza Alex presenting MusicBrainz to his classmates.
Indian student Rayne presenting MusicBrainz to her classmates.
We’re slowly approaching that time of year: Schema change release time. After skipping our fall update to focus on some internal tasks, we’re ready to have another schema change release in the spring: May 16, 2016
We have started the process to collect features we wish to release for this schema change release and we’ll be publishing that list in the coming weeks. However, we’re contemplating the impact of one more change we’d like to make: Upgrading to a more recent version of Postgres.
Internally we are going upgrade to Postgres 9.5, which was recently released, so we expect that the Postgres team will have worked out the most significant kinks before we’re ready to move to it. However, even though we are moving to 9.5, we are considering the impact on our downstream users/customers who need to make the same or similar change.
While we are moving to version 9.5 of Postgres, we have the option of only adopting features from Postgres 9.4, which means that our downstream users may continue to use Postgres 9.4. However, Postgres 9.5 has some nice features we’d like to use (e.g. UPSERT), so we’re pondering if it is possible for us to require Postgres 9.5 from all of ours Live Data Feed users starting on May 16, 2016.
We have already informally queried a few of ours users and so far it seems that requiring Postgres 9.5 is feasible. If you are a Live Data Feed user and feel that this requirement of Postgres 9.5 is too much for your and your organization by May 16, 2016, please leave a comment to this blog post!
Welcome, readers, to the first blog post from the BookBrainz team! I’m Ben (AKA LordSputnik), one of the two guys leading the BookBrainz project to create the most complete and thorough database of literature in the world. Or, in other words, doing for books what MusicBrainz does for music. In this post, I’m going to talk to you about the February 2016 release of BookBrainz, what we’ve been working on, and the current direction of the project.
Unit Testing
One of the biggest areas of work in this update is the new unit testing for the web service. Unit testing allows us to check that our functions work as we expect them to, and help to find and prevent bugs in the code. This is something we’ve been pushing back for months now, and it really needed doing. Luckily, the Google Code-in (GCI) happened, and one of our students, Stanisław Szcześniak, stepped up to the challenge of writing our test suite.
4000 lines of code and several test classes later, our test coverage (the proportion of web service code checked by the tests) has increased from 40% to 70%, and we’ve found about 10 bugs which we’ll be fixing for the next release. Stanisław is still helping out, now focusing his efforts on a BookBrainz plugin for Calibre (like Picard, but for eBooks) and the new BookBrainz client library.
Python Client Library
We’re planning the Python client library to be a key component of a couple of applications we’ll be writing in the future to increase the amount of data in BookBrainz. It’ll also allow outside developers to programmatically access and modify the information in BookBrainz through our web service. At the moment, it’s still in the early stages of development, with Stanisław playing about to find a clean and elegant architecture.
Reactification!
Another area we’re continuing to look into is changing our existing web page templates (written in Jade) to use the React JavaScript library. This helps us by allowing the same code to be used for templating in the browser and the server, and also allows us to use third-party libraries to simplify our user interface code (for example, React-Bootstrap and React-fontawesome).
So far, we’ve converted 9 pages, including login, registration, search and revision display, with a little help from our GCI students. An added benefit of this is that we’ve been able to apply the idea of progressive enhancement to allow JS-enabled browsers to refresh search results in real-time, while keeping the previous functionality for older or limited browsers.
Browser Compatibility
Since the last release, we’ve established a list of supported browsers, and signed up to a really useful automated test site called BrowserStack. This allows us to get screenshots of key pages of the site in many different browsers, and see where things are breaking. Although we’ve been mainly been working on back-end code for the last couple of months, there are a few issues that we’ve found out about in older browsers which will hopefully be fixed soon™. If there are any issues that you’ve spotted when using the site, be sure to let us know in the BookBrainz JIRA.
Improving Error Messages
Working on how we display errors to users is another front-end issue that we’ve sadly been neglecting for about half a year now, in favor of improving the back-end. A good example of the problem is logging in – right now, the site sometimes displays a vague error message about not being able to log the user in, and sometimes it spits out the really unhelpful message “Internal Server Error”.
So informative, BookBrainz…
Part of the work we’ll be doing on error messages in the next few months will involve creating custom error pages and trying to eliminate unfriendly technical error messages. Giving the user a better idea of what to do when something does go wrong is also important, and we’ll be trying to achieve this along with making error display more consistent across the site.
Direct Database Access
The largest change we’ve been working on over the last couple of months is having the site access the database directly, rather than obtaining data through the web service, as we’ve been doing up until now. Originally, we decided to put the web service in between the site and database to ensure that the web service had good data editing functionality and that data representations were the same as those in the site.
However, this led to us having to effectively define our schema three times – once in the database, once for structuring web service data, and once to define the data models used in the site code. We found this to be a bad situation, because it’s easy to forget to keep the three schemas consistent. Last autumn, I tried to improve the web service to automatically generate web service data structures from the site data models, but eventually decided that this would be overly complex and time-consuming.
Instead, we made the decision to migrate all of our code to Node.js, currently used by the site, and then use a shared data model package for both the site code and web service code. With this change, we would only have to define the schema twice – once in the database, and once in JavaScript – better, but not ideal. Thankfully, the Node.js library bookshelf provides database reflection, which means that we can automatically generate the Node.js data models from the database schema, finally removing the need to define the schema in multiple places.
Now, we’re about two-thirds of the way through updating the site to use the new data models – you can see our progress in the GitHub repository. Due to a new emphasis on code quality and implementing tests as we go along, progress has been slow but steady, but this should hopefully result in a more stable site when we complete this upgrade within the next couple of months.
New Web Service
Following the direct database site update, our schema will have changed in subtle ways which will make it impossible to keep using the existing web service code. Ideally, we would have kept the schema unchanged while we moved to Node.js, but partly due to ORM limitations and partly due to a desire to make things better, we’ve been tinkering with it as we’ve gone along.
This means that the web service will be unavailable for a few months while we rewrite it in Node.js. However, the new web service should be a big improvement on the old one, with a more carefully planned design learning from the mistakes of the current iteration. If you have any suggestions for what you think would be a good feature for the new web service, please let us know in the comments!
That’s it from me for now. I hope you’ve found it interesting to get an insight into the things we’ve been working on! For a more specific list of changes in the February 2016 release, please see our change log. If you have any suggestions for our future blog posts, I’d love to hear your feedback.