GSoC 2026: GraphQL Server For Musicbrainz

Hi everyone, I’m Sreehari, also known online as owlpharoah (op3kay on Matrix). I’m a second year student at IIIT Jabalpur. This summer I worked on the foundations of a GraphQL server in Rust that sits over the MusicBrainz PostgreSQL database, under the guidance of @bitmap and @jadedblueeyes.

The Setting

MusicBrainz already has an XML/JSON API, but getting related data out of it means chaining together inc parameters, and browsing support differs from one entity type to the next. Looking up five artists at once isn’t really possible either.

GraphQL fixes most of this by letting a client ask for exactly the fields and relationships it wants in one query. It also lets the server check how expensive a query is before running it, instead of finding out after the database has already taken the hit.

Before writing the proposal, I built a rough prototype covering Artist, Release Group, Release, and Recording, mainly to see how things would click together. Two problems showed up: N+1 queries on relationship fields, and the fact that depth limiting alone doesn’t catch a shallow query that’s still expensive. Both became core parts of the proposal.

The Plan
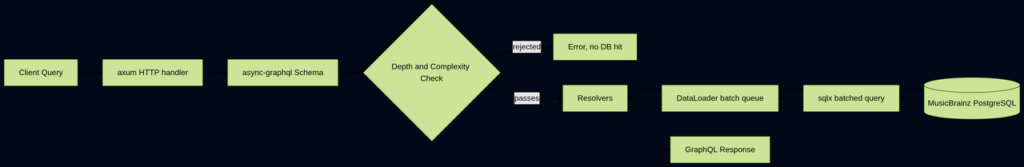
The proposal scoped the project to six entity types: Artist, Release Group, Release, Recording, Label, and Area. Each would be queryable by MBID, with the usual relationships between them, plus aliases, tags, genres, and ratings across the board.

A few decisions were made initially:

  • DataLoaders would follow a two tier split. One loader maps an entity’s internal id to the hydrated entity itself and gets reused everywhere that entity shows up. A separate, thinner loader maps a parent id to a list of child ids.
  • Fields that need a loader call would live behind ComplexObject, so they only run when a client actually asks for them.
  • Pagination would use keyset pagination instead of offset pagination, since offset pagination gets slow and inconsistent on large tables that change often.
  • Query safety would come from depth limiting plus a complexity weight on every resolver.

key goals

  • A working GraphQL server covering the six entity types
  • Schema level depth limiting and query cost analysis
  • A performance baseline from load testing.

The Result

DataLoader infrastructure is in place across all six entities, following the two tier split. Loaders exist for tags, ratings, artist credit, genres, annotations, aliases, ISNI and IPI identifiers, and MBID to internal id resolution. Hydration loaders are shared across every relationship that points at a given entity instead of duplicated per relationship.
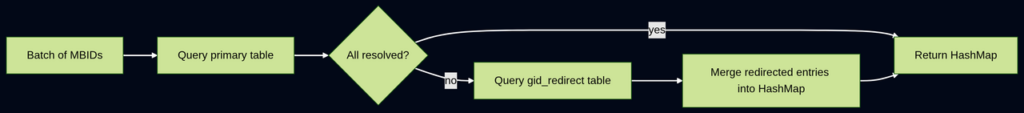
MBID redirect handling lives inside each loader’s load function. When a primary table lookup misses, the unresolved MBIDs get batch queried against the matching *_gid_redirect table, and any hits get merged into the result map. A resolver further up never has to know a redirect happened.

Keyset pagination runs across the paginated fields using ROW_NUMBER() OVER (PARTITION BY parent_id ORDER BY child_id) in a single batched query, so one query can apply a per parent limit across a whole batch of parents. The cursor ended up as a plain integer rather than the opaque string from the proposal.
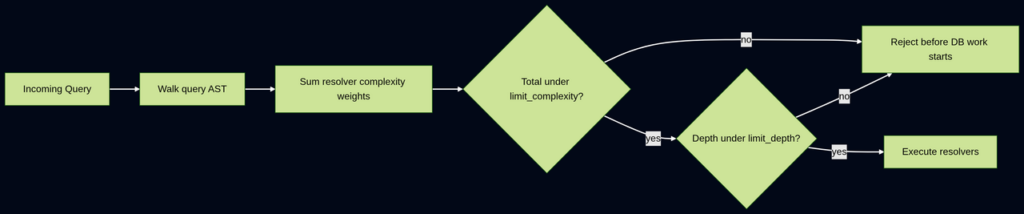
Query complexity weights reflect actual database work: a scalar field costs its default, a single hop DataLoader field costs a flat amount, a paginated one to many field scales with the requested page size, and multi hop fields carry a multiplier on top.

Integration tests cover all six entities.

Week 7’s load testing with k6 turned up two findings worth fixing. There was an N+1 on the isrc field, fixed with a dedicated RecordingIsrcLoader, and a gap in the complexity limiter where a pathological query executed instead of getting rejected outright.

On the infrastructure side, CI runs pre commit hooks and no longer has dead code warnings, and documentation is wired up through Magidoc in Docker compose.

What I Learned

The two tier loader split sounded simple on paper, but it’s saved me a lot of time in practice. Adding a new relationship is now mostly copying hydration logic that already works, instead of writing it fresh.

Fixture data needs to be checked against the database it’s running against, not assumed to be stable. musicbrainz-docker’s sample dumps import non-deterministic subsets of the data, so an MBID that resolves cleanly on my machine can point at something else, or nothing, on someone else’s. That cost me a few confused debugging sessions before I figured out what was going on.

What’s Next

  • Criterion benchmarking, to compare the current per row queries on ComplexObject fields like Release.date against a batched loader variant, and to compare the two hop ArtistCredit and Tags loader patterns against a single joined loader.
  • Moka caching is still an open evaluation.
  • Extended entity coverage beyond the original six.

Conclusion

This was an awesome summer and i enjoyed thinking about and wiring up the API schema and the Postgresql database, fixing bugs, and everything in between. It was really satisfying watching the two tier loader pattern click into place once and then just work for every relationship added after it.

Thanks to my mentors for the guidance, especially on the DataLoader architecture, which I wouldn’t have landed on alone. And thanks to the wider MetaBrainz community for the space to build this in. It’s been a pretty nice summer of query plans, a lot of Rust, and debugging, and I’d do it again.

GSoC 2026: Development of a new Calibre plugin for BookBrainz

Hello, Everyone!

I am Md Waqib Sk (waqib2992 on IRC), an undergraduate student at Indian Institute of Technology Kharagpur. This summer, I had the opportunity to participate in Google Summer of Code 2026 with MetaBrainz, where I worked on developing a calibre plugin for BookBrainz.

I was mentored by Nicolas Pelletier (monkey on IRC). This post summarizes my project, its outcomes, and my experience over the course of the program.

Project Overview

Calibre is a free, open-source e-book manager used to organize and read digital books. My project was about introducing a new plugin that connected calibre with BookBrainz.

The main proposed features of the plugin were:

1. Metadata update: Search selected book from calibre  in BookBrainz database and update it’s metadata accordingly. 

2. Browse BookBrainz: Search editions/public collections by name/bbid  through the plugin and add or download the corresponding metadata.

Plugin Repository: https://github.com/bookbrainz/CaliBBre

Continue reading “GSoC 2026: Development of a new Calibre plugin for BookBrainz”

GSoC 2026: Bringing Internationalization (i18n) to BookBrainz

Introduction

Greetings, everyone!

I am Garv Thakre (@garvthakre:matrix.org on Matrix), an Agentic-AI FullStack Developer . This summer, I had the opportunity to participate in Google Summer of Code 2026 with MetaBrainz, where I worked on the internationalization (i18n) for BookBrainz.

I was mentored by Nicolas Pelletier (@monkey:chatbrainz.org on Matrix). This post summarizes my project, its outcomes, and my experience over the course of the program.

Project Overview

BookBrainz aims to collect information about every book ever written, but until now, the interface was only in English. Since books exist in thousands of languages, having an English-only UI made it tough for non-English contributors to navigate, read, or add metadata.

My main goal this summer was to get BookBrainz ready for translation and set up the foundation so the community can actually start localizing it. Here is what that involved:

Continue reading “GSoC 2026: Bringing Internationalization (i18n) to BookBrainz”

GSoC 2026: Compose Multiplatform Migration of ListenBrainz-Android

Hi everyone,

I’m Nirvan Jain (nirvan_jain on IRC, nirvan73 on GitHub), I’m currently a pre-final year student at IIIT Jabalpur. This summer I was offered this opportunity to work with MetaBrainz through Google Summer of Code on migrating the ListenBrainz android app to Kotlin Multiplatform and Compose Multiplatform, so that most of the same codebase can eventually run on iOS under the mentorship of Jasjeet Singh (jasje on IRC).

This post covers what the project was, everything I worked on, the parts that went wrong, what’s still left, and what the summer was actually like.

How I got here

I started contributing to ListenBrainz in December 2025. It was the first external open source project I’d worked on. Everything before that was coursework, side projects, or intra-college events.

My first PRs were small work which helped me a lot to understand the codebase from the ground, the shimmer effect across the Feed and Profile tabs, then extending search to cover playlists, artists, albums and tracks, plus some bug fixes. Small changes, but they taught me the codebase and how review works when nobody knows you and the code has to stand on its own.

I picked ListenBrainz because music is a constant in my day, whether I’m coding or not, and because I like that it treats your listening history as something you own.

The Problem

ListenBrainz has an Android app but no iOS version. A previous Swift attempt just duplicated the codebase, so every bug fix had to be written twice.

This project solves that by migrating to Kotlin Multiplatform, one shared codebase for both platforms. A large part of the work is replacing Android-only libraries with multiplatform equivalents across navigation, dependency injection and paging. Media playback is the harder case. ExoPlayer and WorkManager are tied too closely to Android to share, so both go behind common interfaces, with ExoPlayer on Android and AVPlayer on iOS underneath.

Getting this foundation right is what makes the rest cheap. Once it’s in place a feature or a bug fix is written once, instead of the same business logic being implemented twice and two apps being kept in sync by hand.

One thing genuinely can’t move. The notification listener that reads what’s playing in Spotify depends on an Android-only permission, and iOS has no equivalent to offer. Those screens stay Android-only. Everything else runs from one codebase on both platforms.

Continue Reading

GSoC 2026: Modernize search storage format for the MusicBrainz database

Hello Everyone!

I’m Junaid (fettuccinae), an undergraduate Computer Science student at MGIT in India. This summer, I returned to MetaBrainz for my second GSoC project, where I worked on modernizing the MusicBrainz search under the mentorship of @kartikohri13 and @bitmap.

Project Overview:

MusicBrainz uses Apache Solr for search queries.
The previous implementation serialized all the response data into a single _store field.
The response writers reads _store, unmarshal the XML into a MusicBrainz XML Metadata Format (MMD) object and then serialize it again as XML or JSON for the response.
Few problems with this design are:
1. The indexer must construct a complete XML representation for every document, even though much of the same information is already available in normal Solr fields.
2. Most of the response data is stored in an opaque _store XML blob.

This project focused on moving the fields from one _store XML blob into their own flat fields (and JSON strings for nested fields).

The main goals of this project were:
1. Upgrade the Solr schema version from 1.5 to 1.7
2. Add fields (in configsets and indexer) to store all the data to be returned
3. Create response writers to return data from fields

The proposal for this project can be found here.

Continue reading “GSoC 2026: Modernize search storage format for the MusicBrainz database”

Welcome Summer of Code 2026 contributors!

We are excited to announce the 7 GSOC participants working with us this summer on MetaBrainz projects!
Our apologies for not publishing this sooner, in this complicated first part of the year we simply forgot the announcement, but rest assured the work is progressing on all projects.

As always, the selection process was incredibly tough. We received a great batch of proposals and had a limited number of slots.
We want to sincerely thank everyone who took the time to meet our community and submit a proposal with us!

The whole list of selected proposals can be found on the GSOC website but here is a TL;DR breakdown:

ListenBrainz proposals:

Integrate MusicBrainz events into ListenBrainz (Shirsak)

MusicBrainz has data about past and upcoming concerts that ListenBrainz users can’t see yet. This project will bring live music events directly into ListenBrainz, allowing you to discover shows tailored to your favorite artists.

Compose Multiplatform Migration of ListenBrainz-Android (Nirvan)

Currently, ListenBrainz has a native Android app but no iOS version. This project will migrate the app to a single, shared codebase using Kotlin Multiplatform. This means future features and bug fixes will launch on both Android and iOS at the same time.

Playlists Sorting and Organization (Yateen)

Giving ListenBrainz playlists a massive user-experience upgrade. Users will soon be able to search through playlists, organize them using custom tags, sort tracks (by artist, title, or date added), and convert their MusicBrainz collections straight into playlists.

MusicBrainz proposals:

Modernize search storage format for the MusicBrainz database (Junaid)

Cleaning up the under-the-hood engine that powers MusicBrainz search (Solr). By upgrading internal configurations and removing data redundancy, this project will optimize performance and make searching for music faster and more efficient.

GraphQL Server as a Musicbrainz API Alternative (Sreehari)

Building a fast, modern alternative way for external developers to request MusicBrainz data. This makes it significantly easier and more efficient for third-party developers to build apps using our database.

BookBrainz proposals:

Set Up BookBrainz for Internationalization (Garv)

Breaking down language barriers! BookBrainz is currently English-only. This project lays the technical groundwork to support multiple languages and sets up a BookBrainz project on translations.metabrainz.org where volunteer translators can start translating the site immediately.

Development of a new Calibre plugin for BookBrainz (Waqib)

Connecting BookBrainz with Calibre (the popular e-book management software). This plugin will allow Calibre users to automatically pull book metadata and collections directly from BookBrainz to organize their personal digital libraries.

What if you’re not in GSoC 2026?

Reading this and feeling inspired for contributing to the code still? Volunteer contributors are very welcome all year round even though we might have slightly less time available to help you during the summer. It is also putting you in an ideal situation for applying to next year’s GSoC. You can find some tips for applying to GSoC with us in one of our previous posts. When you are ready, join us on the MetaBrainz Matrix Channel and showcase your initiative and your skills!

GSoC 2025: Building Libretto, a Matrix Archiver

This post is also available on Jade’s blog

Hello! I’m Jade Ellis, AKA JadedBlueEyes. You might know me from my project with MetaBrainz last year – if not, I’m happy to have the chance to introduce myself. I’m an undergraduate Computer Science student at the University of Kent in England, a music enthusiast and (in my spare time) a climber.

The Setting

In September 2024, MetaBrainz switched from IRC to Matrix as our primary form of communication. Matrix is a more feature-rich alternative to IRC, with capabilities like replies, edits, and reactions, while still being open source and aligning with the principles of our project.

When MetaBrainz primarily used IRC, we had a piece of software called BrainzBot. This was a multi-functional Python app that, most importantly, created a web-accessible archive of all messages in the MetaBrainz channels. Thanks to the bridges between IRC and Matrix, BrainzBot continued to trundle along, but it couldn’t understand modern features like edits, replies, or media. The code itself was also becoming decrepit—a fork of an abandoned project, showing its age.

This led to my GSoC project: to build a replacement for BrainzBot’s archival function – a chat archiver that natively understands and preserves Matrix’s rich features.

Continue reading “GSoC 2025: Building Libretto, a Matrix Archiver”

GSoC 2025: Onboarding Revamp in ListenBrainz Android

Hi everyone,

I’m Hemang Mishra (hemang-mishra on IRC and hemang-mishra on GitHub). I’m currently a pre-final year student at IIIT Jabalpur, India. This summer, I had the opportunity to participate in Google Summer of Code with MetaBrainz. My mentor for the program was Jasjeet Singh (jasje on IRC).

I contributed to ListenBrainz Android, where I worked on revamping the onboarding experience, improving login, adding listen submission apps, integrating Listening Now, and setting up app updates. The journey has been both exciting and full of learning, and I’m truly grateful for this opportunity.

Project Overview

ListenBrainz is a powerful platform that helps track listening history, share music tastes, and build a community around music.

The main goals of my project were:

  • Revamping onboarding – introducing users to the app’s core features and handling permissions with clear rationale.
  • Improving login –replacing simple web pages with a custom Compose-based UI, and experimenting with the DOM tree of the web page to automate form submissions and token extraction in the background.
  • Listen submission apps – prompting users during onboarding to select which apps to collect listens from, preventing unwanted submissions.
  • Listening Now integration – adding “Listening Now” into BrainzPlayer.
  • App updates – enabling updates for both Play Store and non-Play Store (F-Droid or sideloaded) releases.
Continue reading “GSoC 2025: Onboarding Revamp in ListenBrainz Android”

GSoC 2025: MetaBrainz Notification System

Hello, my name is Shaik Junaid (IRC nick fettuccinae and fettuccinae on GitHub). I’m an undergrad computer science student from MGIT, Hyderabad, India. My project focused on adding a central notification system for MetaBrainz.

Project Overview

This project’s idea was suggested to me by mentor @ruaok (AKA mayhem on IRC). I submitted my proposal on the MetaBrainz Forum and got it reviewed by @kartikohri13 (AKA lucifer on IRC), and finally got selected for GSoC 2025 .

A centralized notification management system will various MetaBrainz projects send notifications to users without rewriting boilerplate code. It will also keep users informed about the latest events and new features across projects. This is a goal bigger than the scope of a single GSoC project. To keep it reasonable, my project focused on implementing REST APIs, hosted on metabrainz.org, to manage notifications and user preferences for notifications. Additionally, I integrated the system with ListenBrainz to demonstrate its functionality.

The project spec sheet can be found here.

Continue reading “GSoC 2025: MetaBrainz Notification System”

GSoC 2025: Advanced User Statistics Visualizations

Greetings, Everyone!

I am Granth Bagadia (holycow23 on IRC), an undergraduate Computer Science student at Birla Institute of Technology and Science (BITS), Pilani. This summer, I had the opportunity to participate in Google Summer of Code 2025 with MetaBrainz, where I worked on introducing advanced user statistics visualizations for ListenBrainz.

I was mentored by Ansh Goyal (ansh on IRC), Kartik Ohri (lucifer on IRC), and Nicolas Pelletier (monkey on IRC). This post summarizes my project, its outcomes, and my experience over the course of the program.


Project Overview

ListenBrainz already provided some listening statistics, but these were limited in scope and depth. My project set out to design and implement advanced statistics that could offer users more meaningful insights into their listening habits. Since ListenBrainz is a user-centric platform, the idea was to create features that would let listeners explore their behavior from multiple perspectives. My original proposal focused on introducing a few key statistics.

The core statistics included:

  • Genre Trends – showing what genres a user listens to at different hours of the day.
  • Era Statistics – highlighting which musical eras dominate a user’s listening history.
  • Artist Evolution – tracking how much a user listens to specific artists over time.
Continue reading “GSoC 2025: Advanced User Statistics Visualizations”