Classical Community Cleanup #1: Debussy

The Metabrainz Classical Music Enthusiasts Team has kicked off to a strong start! If you are unaware about the formation and tasks at hand, you can read more about it on the forums.

It’s clear by the number of discussions and engagements in the forum that a community effort on classical music was long overdue! It’s thrilling and we are eager for the first mission: after some discussion and voting we decided that the first community effort would be a clean-up of all our data for Claude Debussy.

As a composer with a huge influence in 20th century music, yet with a relatively low amount of hard to edit compositions like operas, Debussy is a great first choice for the community of classical editors to start actively working together to improve the data. As such, if you’d like to help out, but are new to classical editing or not too active in the community yet, don’t hesitate to reach out and ask any questions. The classical community is active in its own forum category, and we’re hoping to see a lot of activity there with editors both asking and answering questions.

What will we be working on in this first classical cleanup project?

  • We will review the existing works and catalogues to make sure there are no duplicates and the info looks correct (several very active classical editors have already been working on this in preparation for this cleanup).
  • We will check the release list for anything that doesn’t follow the classical guidelines. Those should of course be fixed to follow the guidelines, and that’s usually a good sign of the recording and relationship info being incomplete as well.
  • We will work on the recording list. The only recordings that should be there by the end of the cleanup are of Debussy himself as a performer. Anything else currently there should have performer relationships added to it if missing, then the artist credits for the recording should be changed to list the main performers.
  • And we will add missing Debussy recordings! If you have enough info to add a release we’re missing that includes works by Debussy, that’s always useful. Just make sure to try to add as much info as possible from the get go, so we don’t have to clean that addition up as well!

Don’t know where to begin? Let us know and we can help find a starting point–or just jump in and help out! We can’t wait for Mr. Debussy to be a great example of how much information MusicBrainz can provide!
ListenBrainz data is live on BigQuery!

We’re pleased to announce that in cooperation with Google, we are live streaming our ListenBrainz data to Google’s BigQuery service!

ListenBrainz is a project is that has the potential to gather a lot of data quickly, which would require us to have a Big Data infrastructure, which can be expensive. In an effort to use our available cash wisely, we began to look around for ways to take advantage of other infrastructures with lower costs.

Two years ago at the Google Summer of Code mentor summit I met with a representative from the BigQuery team who said that Google was happy to host any public data set for free! I immediately took them up on this offer and started a conversation.  With much time passed, we finally managed to get the data set live!

If you wish to play with the data, please do!

https://bigquery.cloud.google.com/table/listenbrainz:listenbrainz.listen

You’ll need a Google account to log in with — once you’re logged in, every user gets 5TB of query traffic free per month. That is quite a lot for how large this dataset is currently. The schema for this table is defined here and what the data elements mean are defined in our API docs. To get you started, I’ve written a few sample queries:

BigQuery uses an SQL like syntax, so if you know some SQL then diving right in should be easy. The queries above should give you an idea of what you can do with this data. Now, please know that currently we have approaching 30M listens, so the dataset is still quite small. We’re very much interested to see what sort of things people can come up with in the near future.

Finally, some notes about openness and proprietary software: Given that we have limited resources, we aim to make the most things happen with the services that are at our disposal. Google has been extremely generous to us over the years and we’re very pleased to have access to BigQuery now.

That is not to say that we’re putting all of our eggs in one basket or forcing people to use BigQuery. Our InfluxDB database hosted on our own servers keeps the master archival copy of our listen data. Soon we hope to make dumps of this data available for anyone to download and play with using whatever tools they would like. With this setup we are not fully reliant on Google for keeping this project alive. We’re glad to have their support, but should circumstance change, we can find another BigData solution and load our master archival copy there.

Now, go play with this very promising data and post some of your favorite queries in the comments!


ListenBrainz enters Beta stage

I’m pleased to announce that we released our first official beta version of ListenBrainz yesterday! As you may know, ListenBrainz is our project to collect, preserve and make available, user listening data similar to what Last.fm has been doing, but with open data.

In 2015 a small group of hackers gathered in London to hack on the first version of ListenBrainz alpha. We threw together a pile of new technologies and released the first version of ListenBrainz at the end of the weekend. In the end, we didn’t really like the new technologies (Cassandra, Kakfa) as both ended giving us a lot of problems that never seemed to end.

In 2016 we embarked on a journey to pick new technologies that we liked better and ended up setting on InfluxDB and RabbitMQ as backbones to our data ingestion pipeline. These tools were a good match for us, since we were already using them in production! Sadly, MetaBrainz’ move to our new hosting provider ended up sucking up any available time we had to devote to the projects, so progress was made in fits and starts.

Earlier this year Param Singh expressed interest to help with the project in hopes of joining us for a Google Summer of Code project. He started submitting a never ending stream of pull requests; slowly the project started moving forwards. Together we brought the codebase up to our current standards and integrated it into the workflow that we use for all of the MetaBrainz projects.

We proceeded to prepare the next version to be released at MetaBrainz’s new hosting facility and started a never ending series of tests. We kept pounding on the data ingestion pipeline, trying to find all of the relevant bugs and ways in which the data flow could get snagged. Finally the number of reported bugs relating to data ingestion dropped to zero and we managed to import 10M listens (a listen is a record of one song being played)!

That was our cue for promoting our pre-beta test to a full beta and unleashing it onto our production servers at our new hosting facility. Today we cleaned up the last bits of the release and we are ready for business!

What does this new release bring for you, the end users? Sadly, only a few new things, since most of the work has gone into building a stable and scalable system. We do have a few new things in this release:

  • Incremental imports from Last.fm — now you don’t have to do a full import any time you wish to import your latest listens from Last.fm. The importer knows when you last did and import and will work accordingly.
  • Last.fm compatible submission interface — with some system configuration changes you can submit your listens directly to ListenBrainz from any application with Last.fm support. (more info here)
  • Last.fm file import — if you have an old skool Last.fm zip file with your listening history backed up, you can now import it.
  • User data export — you can now download your own listens straight from the site, no waiting required.
  • Adaptive rate limiting on the API — our server now uses a modern rate limiting system. For details, see our API docs.

The good news is that Param is now working on his Summer of Code project that will add a lot of graphs and other critical elements for making use of this new data set. We hope to release new features on an ongoing basis from here on out.

Most importantly, we want to publicly state that ListenBrainz is now ready for business! We don’t plan to reset the database from here on out — this is the real deal and we plan to safeguard and make this database available as soon as we can. If you have hesitated with sending your listen histories to ListenBrainz in the past,  you should now feel free to send your listen information to us! If you are an author of a music player, we ask that you consider adding support for ListenBrainz in your player!

In a follow-up blog post I am going to write about how to start using ListenBrainz now — at the very least use it to back-up your Last.fm listening history!

If you find bugs with our latest release, please report them to our issue tracker. If you’re interested in this project and have questions for us, why not come and pop into our IRC channel or ask a question on our community forum?

P.S. The alpha version of ListenBrainz is still around.

P.P.S. We’ll have another cool announcement very shortly! Stay tuned!

Server update, 2017-07-17

In order to deter spammers, bios and homepages can no longer be set by limited users (accounts less than 2 weeks old, or with less than 10 accepted edits).

Thanks to ferbncode, Sophist, and yvanzo for their work on the tickets below.

The git tag is v-2017-07-17.

Bug

  • [MBS-9342] – InitDb.pl fails to import data with DBD::Pg 3.6.0
  • [MBS-9372] – Revoking editing/voting editor rights also renders them unable to write edit notes
  • [MBS-9392] – JSON-LD schema.org structured data broken
  • [MBS-9401] – SQL generation fails for release groups (script/dump-entities-sql.pl)
  • [MBS-9403] – position attribute is missing in the json api output for media > track

Task

  • [MBS-9355] – Do not allow an editor to set bio/link if the user is limited
  • [MBS-9391] – Retry downloading dumps in docker container (for creating and importing dumps)

Improvement

  • [MBS-9323] – Artist web page with long wikipedia entry looks bad

MusicBrainz User Survey

It’s hard to stress how much MusicBrainz depends on the community behind it. In 2016 alone 20.989 editors made a total of 5.935.653 edits at a continuously increasing rate.

But while MusicBrainz does collect data on a lot of different entities, its users are not one of them, and the privacy policy is pretty lean.
Unfortunately this does make it fairly difficult to find out who you are, how you use MB and why you do it.

Seeing as this kind of information is fairly important for the upcoming project of improving our user experience, I volunteered to create a survey to allow you to tell us how you use MB, what you like about it and what you don’t like quite as much.

So without further ado, click on the banner to get to the survey: (It shouldn’t take more than 15 minutes of your time.)
MusicBrainz User Survey

Now if you’re still reading this blog post, that hopefully means you’ve already completed the survey! I’d like to thank Quesito who joined this project earlier this year and has been a great deal of help, our former GCI student Caroline Gschwend who helped with the UX part of the survey, CatQuest who has been around to give great feedback since the first draft and of course also all the other people who helped bring this survey to the point of release.

If you’ve got any feedback on or questions about the survey itself, please reply to the Discourse forum topic.

Server update, 2017-06-19

This release mainly fixes some bugs around reorganized lyrics languages for work, and includes a few small improvements. Thanks to Zastai for fixing events browsing for area.

The git tag is v-2017-06-19.

Bug

  • [MBS-8757] – Error browsing events by area
  • [MBS-9338] – Can’t add languages to existing works that have none set
  • [MBS-9341] – “0 field is required” if work language is selected, then blanked
  • [MBS-9345] – Can’t batch-add works without a language set
  • [MBS-9347] – Regression: “- MusicBrainz” is appended to homepage title instead of others
  • [MBS-9362] – Work language edits preceding schema change are not applied

Task

  • [MBS-9354] – Block /collection as per robots.txt

Improvement

  • [MBS-8640] – Make adding work attributes auto-edits
  • [MBS-9311] – Add autoselect and validation of CD Baby Artist-URL relationship
  • [MBS-9348] – Update CD Baby URLs normalization and sidebar display
  • [MBS-9350] – Add autoselect/sidebar for Big Cartel URLs

OpenScore: Liberating Sheet Music

MetaBrainz sponsored Music Hack Day London 2014 and we had agreed to provide a prize for one of the winners. We thought that Thomas Bronte from MuseScore had the best hack and offered him a choice of a few prizes that were appropriate for hack day winners. Thomas declined and instead asked if he could pen a guest blog entry on our blog when they were ready to reveal their new project. We immediately agreed to do that, since open source projects need to stick together and help each other out. Finally, this is the blog post that Thomas and crew penned—read on to find out about their excellent new project!


Composers

OpenScore is a new crowdsourcing initiative to digitise classical sheet music by composers whose works are in the public domain, such as Mozart and Beethoven. Massive crowdsourced projects like Wikipedia, Project Gutenberg and OpenStreetMap (not to mention MusicBrainz!) have done wonders for the democratisation of knowledge, putting information and power in the hands of ordinary people. With OpenScore, we want to do the same for music.

OpenScore’s aim is to transform history’s most influential pieces from paper music into interactive digital scores, which you can listen to, edit, and share. This will be of huge benefit to orchestras, choirs, ensembles, and individuals looking for materials from which to practise music, but it doesn’t end there! All OpenScore sheet music editions will be freely distributed under Creative Commons Zero (CC0). This means there are no restrictive copyright terms, so everyone will be free to use the files for any purpose. We want to maximize the benefit to music education and research, and inspire composers and arrangers to produce new content.

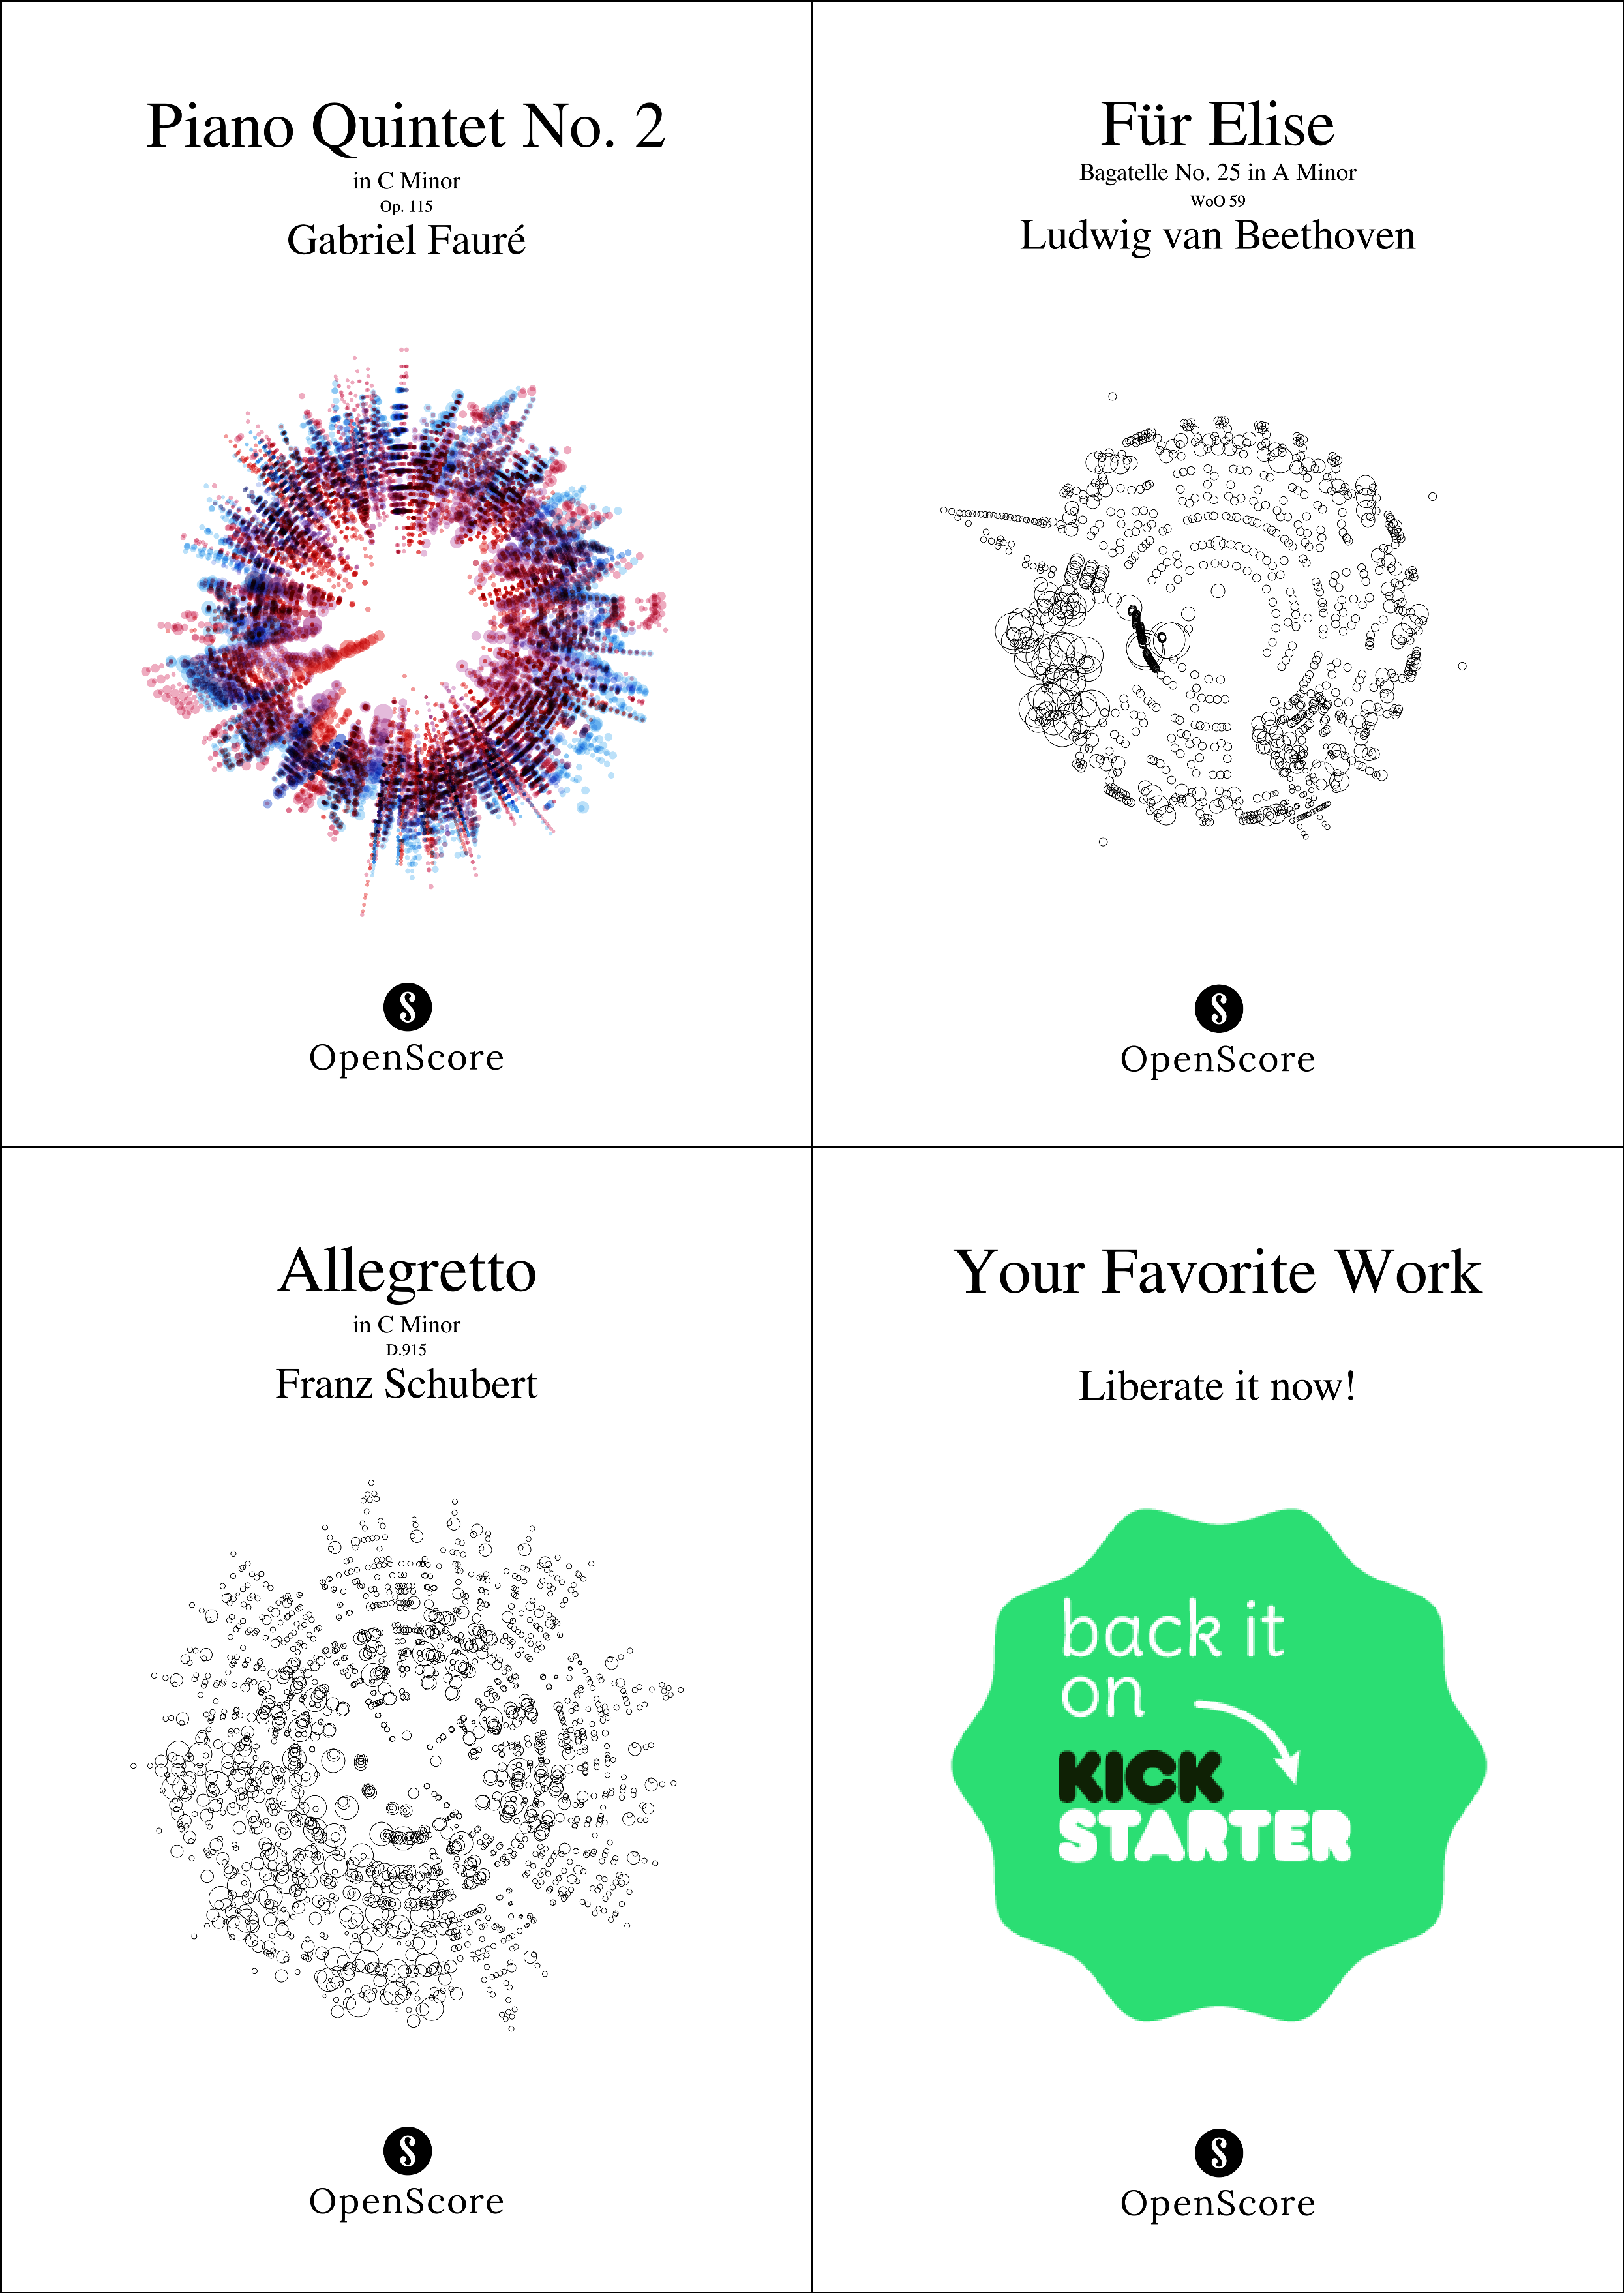
Four covers
OpenScore Editions of various classical works

The advantages of digital sheet music are huge. OpenScore Editions will be available in the popular MusicXML format which can be read by most music notation programs. The files can also be parsed by software tools for research and analysis, and can even converted to Braille notation for blind musicians. Digital scores can also be easily adapted into non-standard forms of notation for use in education, accessibility, or gaming; or turned into artistic visualisations. The works will be stored in an online database, accessible via a REST API. Each work will be associated with its composer’s MusicBrainz and WikiData IDs to enable cross referencing with existing online content.

OpenScore is the result of a partnership between two of the largest online sheet music communities: MuseScore and IMSLP. Since 2006 the IMSLP community has been searching for out-of-copyright musical editions, scanning and uploading them to create one of the world’s largest online archives of public domain sheet music in PDF format. MuseScore has a dedicated community of millions of people around the world, who use MuseScore’s website and open source notation software to compose, arrange, practise and share digital sheet music. OpenScore will harness the power of these communities to transcribe the IMSLP editions, which are currently just pictures of pages, into interactive digital scores by typing them up, one note at a time, into MuseScore’s sheet music editor.

OpenScore starts with a Kickstarter campaign to liberate 100 of the greatest classical pieces. This will help us to start developing the necessary systems to scale up to liberating all public domain music. Backers can help pick the pieces to be liberated, so if you love classical music and you wish to liberate a composer or a specific work, make sure you support the Kickstarter campaign and help spread the word about OpenScore and digital sheet music!

Community Recap April 2017

Hello, and welcome to the April recap of what’s happened in MetaBrainz land!

Compared the first quarter, April was somewhat on the slow side (reflected on the blog with only three posts that month). I’m guessing this is a mix of both recovering from all the activity in the first few months and a lot of work going on in the background—incl. preparing for Google Summer of Code. However, some stuff did happen, so let’s talk about those things! Continue reading “Community Recap April 2017”

Instruments part two: tamburica, hybrids, community links, and growing pains!

Continuing our story from last time…

tamburica instrument family tree
By now I was starting to get a bit more comfortable in my role as Instrument Inserter. I went about doing a bit more in-depth research, especially for the tamburica, and I made a post on the forum where I asked for input researching these instruments.
Eventually I mean to come back to this group of instruments (and in fact this is what I am doing currently), expanding the family tree I’ve been working on, which is why this “fix” version is still open.

Tamburica: 2017 January 6th to the 25th:

New Feature

    • [INST-64] – add the instruments of the Balkan tamburica orchestra; was: Contratambura
    • [INST-455] – (Indian) tanpura
    • [INST-529] – samica/dangubica/kutrevka
    • [INST-457] – clean out and clarify “tambura”   (still open)

Initially, what I found to be the hardest part of adding instruments was actually the addition of aliases. It was a cumbersome, time consuming and annoying part, and I often clamoured for someone to write some sort of Batch Alias script. Then, in March, loujine came in like a superhero with a batch alias script! Now thanks to this script I can add aliases en masse, which has helped me tremendously!

After reosarevok fixed INST-723, I could link hybrids with the instruments they were hybrids of, therefore a batch of “hybrid” instruments came next.

Hybrids: 2017 February to March:

New Feature

Task

  • [INST-461] – Add the Wikidata link for the mirliton
  • [INST-462] – Add ヴァイオリン alias to violin
  • [INST-463] – Add コントラバス alias to double bass

Improvement

  • [INST-458] – English Horn – Cor anglais
  • [INST-459] – Correct Wikidata link for the three-hole pipe

By this time a community discussion came out about the use of disambiguations and descriptions (instrument exclusive fields, which, unlike disambiguations, are translatable), with some users suggesting they were too long, some pointing out issues with translating and yet others suggesting the description field should be dropped altogether. While this discussion didn’t reach a clear resolution, it’s definitely something we should revisit later.

Stay tuned for part three!

Broken replication packet fix (#104949)

If your replicated slave threw an error trying to apply packet #104949 (showing the message ERROR: duplicate key value violates unique constraint "artist_alias_idx_primary"), then you can un-break things by doing the following:

    1. Get the latest code from the master branch:
      git checkout master && git pull origin master (OR, if you don’t want to update your code, clear the dbmirror_pending tables instead:
      echo 'TRUNCATE dbmirror_pending CASCADE; TRUNCATE dbmirror_pendingdata CASCADE;' | ./admin/psql READWRITE)
    2. Proceed with replication as normal, either via cron, or by running ./admin/replication/LoadReplicationChanges

You can also re-import from dump 20170605-031203 or later, and replicate from there. We’re very sorry for the inconvenience.

The issue here was caused by a bug in our alias merge code that interacted strangely with dbmirror. Since that code went untouched for years, the trigger for this issue must have been extremely rare. I’ve put in place a fix for the merge logic to ensure it doesn’t happen there again, and am investigating dbmirror’s behavior to see why it didn’t sequence the updates correctly.