Instruments part two: tamburica, hybrids, community links, and growing pains!

Continuing our story from last time

tamburica instrument family tree
By now I was starting to get a bit more comfortable in my role as Instrument Inserter. I went about doing a bit more in-depth research, especially for the tamburica, and I made a post on the forum where I asked for input researching these instruments.
Eventually I mean to come back to this group of instruments (and in fact this is what I am doing currently), expanding the family tree I’ve been working on, which is why this “fix” version is still open.

Tamburica: 2017 January 6th to the 25th:

New Feature

    • [INST-64] – add the instruments of the Balkan tamburica orchestra; was: Contratambura
    • [INST-455] – (Indian) tanpura
    • [INST-529] – samica/dangubica/kutrevka
    • [INST-457] – clean out and clarify “tambura”   (still open)

Initially, what I found to be the hardest part of adding instruments was actually the addition of aliases. It was a cumbersome, time consuming and annoying part, and I often clamoured for someone to write some sort of Batch Alias script. Then, in March, loujine came in like a superhero with a batch alias script! Now thanks to this script I can add aliases en masse, which has helped me tremendously!

After reosarevok fixed INST-723, I could link hybrids with the instruments they were hybrids of, therefore a batch of “hybrid” instruments came next.

Hybrids: 2017 February to March:

New Feature

Task

  • [INST-461] – Add the Wikidata link for the mirliton
  • [INST-462] – Add ヴァイオリン alias to violin
  • [INST-463] – Add コントラバス alias to double bass

Improvement

  • [INST-458] – English Horn – Cor anglais
  • [INST-459] – Correct Wikidata link for the three-hole pipe

By this time a community discussion came out about the use of disambiguations and descriptions (instrument exclusive fields, which, unlike disambiguations, are translatable), with some users suggesting they were too long, some pointing out issues with translating and yet others suggesting the description field should be dropped altogether. While this discussion didn’t reach a clear resolution, it’s definitely something we should revisit later.

Stay tuned for part three!

What’s going on with instruments anyway? (part 1)

Hi everyone! I’m CatQuest, the Endeavouring MusicBrainz Instrument Inserter. I’ve been meaning to write a post or two about this for a while, but now finally everything is in order!

As some of you may know, I have “officially” taken over instrument additions from reosarevok. I suggested this way back in June 2016 because a) reo was already overworked enough between doing Style, handling support, dealing with social media, and other things, and b) as a consequence of this, the Instrument Requests queue had grown unmanageably large.

Initially I started without grouping, components, or “fix versions”, but later I’ve been allowed to organise everything to my liking and so, I’ve gone back and retroactively added tickets for initial batches, modelled on freso’s ORG tickets.

So without further ado: Here is a list of the instrument tickets I solved from my initiate appointment in July 2016 to roughly October:

Very first batch:

New Feature

It felt natural to separate this at Pipe and Tabor, so the next batch got a different “fix” version, from October to (taking a Christmas break) January 2017:

Second batch:

Bug

New Feature

Improvement

Stay tuned for part two!

Schema change release, 2017-05-15 (including upgrade instructions)

We’re happy to announce the release of our May 2017 schema change today! Thanks to all who were patient during today’s downtime as we released everything to our production servers.

This is a fairly minor release as far as schema changes go, but please do report any issues that you come across.

Currently, the only visible change for editors is the ability to add multiple lyrics languages to works. We’ve also modified the schema to support dynamic attributes for entities other than works, but the UI for that won’t be complete for another release or two.

Now, on to the instructions.

Schema Change Upgrade Instructions

Note: Importing the latest data dump is always a valid alternative to running ./upgrade.sh on an existing database, if you’d prefer to also get new data in one go. Just follow the relevant instructions in INSTALL.md. The rest of the instructions here assume an in-place upgrade.

  1. Make sure DB_SCHEMA_SEQUENCE is set to 23 in lib/DBDefs.pm.
  2. If you’re using the live data feed (your REPLICATION_TYPE is set to RT_SLAVE), ensure you’ve replicated up to the most recent replication packet available with the old schema. If you’re not sure, run ./admin/replication/LoadReplicationChanges and see what it tells you; if you’re ready to upgrade, it should say “This replication packet matches schema sequence #24, but the database is currently at #23.”
  3. Take down the web server running MusicBrainz, if you’re running a web server.
  4. Turn off cron jobs if you’re automatically updating the database via cron jobs.
  5. Switch to the new code with git fetch origin followed by git checkout v-2017-05-15-schema-change.
  6. Run cpanm --installdeps --notest . (note the dot at the end) to ensure your perl-based dependencies are up to date.
  7. Downgrade DBD::Pg by running cpanm TURNSTEP/DBD-Pg-3.5.3.tar.gz (version 3.6.0 breaks things currently).
  8. Run ./upgrade.sh (it may take a while to vacuum at the end).
  9. Set DB_SCHEMA_SEQUENCE to 24 in lib/DBDefs.pm as instructed by the output of ./upgrade.sh.
  10. Turn cron jobs back on, if applicable.
  11. Restart the MusicBrainz web server, if applicable. It’s also recommended you restart redis. If you’re accessing your MusicBrainz server in a web browser, run npm install followed by ./script/compile_resources.sh.

For those curious, here’s the list of resolved tickets (excluding MBS-8393):

Bug

New Feature

  • [MBS-9271] – Prevent usernames from being reused

Task

  • [MBS-9273] – Fix the a_ins_edit_note function in older setups to not populate edit_note_recipient for own notes
  • [MBS-9274] – Fix the edit_note_idx_post_time_edit index in older setups to handle NULL post_time

Improvement

  • [MBS-5452] – Support multiple lyric language values for works

Picard 2.0 dev available via PyPi

Sambhav’s GSoC project is all about Picard 2.0, and among progress made the devel version is now installable via PyPi: https://pypi.python.org/pypi/picard_dev

To install the dev builds you need to have a Python 3.5 or greater. At the moment it is mainly a port of 1.4.x to Python 3 and Qt5, with support for HiDPI and new icons !

Please note that Picard Dev version uses a different config file than your stable Picard installation. As such the settings and plugins will be on their default configuration.

To use your stable config with the dev version, simple copy your “Picard.ini” file from your MusicBrainz user folder to “Picard Dev.ini” which can be found in the same folder.

Since testers may want to run a stable 1.4.x version along the 2.0 dev one, the executable is named “picard_dev”.

Of course, we encourage people to test this version on every platform they can, and report any issue.

Thanks to Sambhav Kothari for the fantastic job he did on this ! And stay tuned, more to come !

Picard 1.4.2 released

Official MusicBrainz cross-platform music tagger Picard 1.4.2 is now out.

This is mainly a bugfix release, the only notable improvement is related to TOPE/TOAL tags.

Users can get Windows and MacOSx packages from Picard website downloads section.

Bug

  • [PICARD-1053] – Picard does not stop analyzer while moving
  • [PICARD-1055] – picard hangs with: RuntimeError: maximum recursion depth exceeded in cmp
  • [PICARD-1070] – The “Convert Unicode punctuation characters to ASCII” function only works in certain tags
  • [PICARD-1077] – ID3v2.4 text encoding settings are not saved correctly

Improvement

  • [PICARD-969] – Search dialog webservices get queued behind matched album requests
  • [PICARD-1034] – Picard not seeing TOPE and TOAL

Picard 1.4.1 released

Official MusicBrainz cross-platform music tagger Picard 1.4.1 is now out, it contains few fixes and enhancements, plus few extra features that didn’t make it to 1.4.

As usual you can get Windows and MacOSx packages from Picard website downloads section.

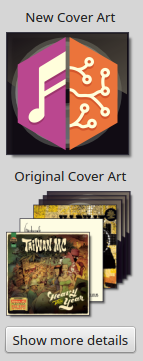
Most notable changes are the fix of a regression concerning drag-n-drop on MacOSx and improved cover art box, with better visual feedback about changes in cover art images.Capture du 2017-04-01 14:40:58

Thanks to all contributors who helped on this release: Antonio Larrosa, Frederik “Freso” S. Olesen, Laurent Monin, Lukáš Lalinský, Sambhav Kothari, Sophist, tungol, Ville Skyttä, Wieland Hoffmann.

And to all of our translators!

To report any issue about this release, please use our bug tracker. As usual you can also get help on the forum or on IRC (freenode, #musicbrainz).

We’ll now focus on 2.0, which will be mostly a port of 1.4.x to Python 3 and Qt5.
It will open the way to UI improvements, and improved overall performance.

Bug

  • [PICARD-953] – Album shown matched even if extra unmatched files
  • [PICARD-972] – Removing album with saves pending does not remove pending saves
  • [PICARD-973] – Pending log messages not flushed to stderr on quit
  • [PICARD-988] – Drag & Drop not working
  • [PICARD-990] – Picard violating ID3 standard for TXXX frames
  • [PICARD-996] – Disabling the cover art box and enabling it again doesn’t bring it back
  • [PICARD-998] – Disabling the action toolbar sometimes doesn’t work
  • [PICARD-1005] – If a cluster is moved to the album side of the main window it gets moved to unmatched files
  • [PICARD-1006] – Drag and drop for cover arts doesnt work on OSX
  • [PICARD-1010] – Unsetting View/Cover Art doesn’t work permanently
  • [PICARD-1011] – Toolbar tab order incorrect after PICARD-908
  • [PICARD-1014] – Number of images in release info is calculated incorrectly
  • [PICARD-1015] – Artwork tab of the Track Info DIalog doesn’t show changes anymore
  • [PICARD-1018] – CoverArtBox doesn’t show new/removed images after unmatched files are added/removed to the album
  • [PICARD-1023] – Directory persistence for Add Directory needs tweaking
  • [PICARD-1029] – Fix ~artists_sort metadata variable
  • [PICARD-1042] – Missing import for PICARD_APP_NAME

New Feature

  • [PICARD-258] – Visual feedback for changes to artwork in before-after pane.
  • [PICARD-1000] – Implement artwork diff for albums

Task

  • [PICARD-943] – Remove monkey patching of file write methods in picard formats
  • [PICARD-1041] – Replace Ok button text by Make It So! in Options dialog

Improvement

  • [PICARD-223] – Remove should work when Unmatched Files is selected
  • [PICARD-666] – Drop MP3 tagging support
  • [PICARD-951] – Always use HTTPS for musicbrainz.org
  • [PICARD-952] – Use Cover Art Archive over HTTPS
  • [PICARD-961] – Mention AcoustID on Scan button too
  • [PICARD-980] – Drag&drop cover art doesn’t work for images from amazon/google images/https links
  • [PICARD-1012] – Buttons on the “User Interface” and “Scripting” pages are smaller than buttons in other places
  • [PICARD-1016] – Multiple images in related tracks confusing
  • [PICARD-1021] – Picard loads all pending files before quitting
  • [PICARD-1024] – Allow specifying a configuration file path
  • [PICARD-1030] – Allow to add/replace cover art images and keep existing cover art

Picard 1.4 released

Official MusicBrainz cross-platform music tagger Picard 1.4 is now out, containing many fixes and new features!
The last time we put out a stable release was more than 2 years ago, so a lot of changes have made it into this new release. If you’re in a hurry and just want to try it out, the downloads are available from the Picard website.

Picard 1.4

picard-1-4-screenshot
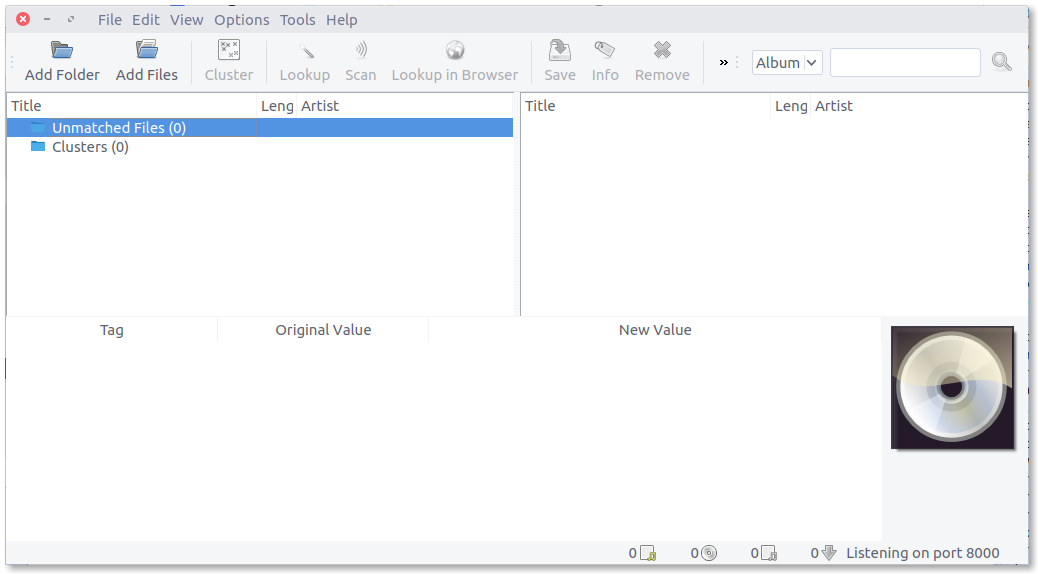
A brand new Picard 1.4 install, fresh from the oven. Get it while it’s hot!

2 years is a long time for software, and Picard has been the subject of a couple of Google Summer of Code projects and plenty of developments required by changes in dependencies and the MusicBrainz project itself. Overall, the changes would be too numerous to list. If you’re curious to read it all, a complete list of changes can be seen on the website. Here are at least a few of the highlights: Continue reading “Picard 1.4 released”

Google is awesome: How should we spend $5000?

The Google Open Source Programs office is amazing!

In the past few years Google has sponsored our summit where we gather a pile of MusicBrainzers into one room and talk shop (and a bit of play) for a whole weekend. But, due to extenuating circumstances and our move to NewHost, we opted for a much smaller and lower key developer gathering in Barcelona. As a result we didn’t spend much money and I opted to not pester Google to support our summit as they have in the years past.

Then yesterday the lovely Cat Allman from OSPO send us a PO for $5000 and a stern reminder to send an invoice soon. After explaining the situation to Cat, she still felt it was appropriate to collect the money and to “use the money as best serves the project.” 

Wow, thank you!

The question I have, for all of our readers, contributors, editors, hackers and advocates: How do you think we should spend $5000 to best serve MusicBrainz and its sister projects?

I’ll leave it wide open to everyone to chime in — feel free to put suggest anything reasonable and meaningful in the comments. Please do the skip the “send it to me!” type comments. 🙂

Finally, I want to thank Google for its continued support of our projects. Through its annual support of $40,000, Summer of Code, Code-In, the paid data license for its Knowledge Graph and the support of our summit, Google is the biggest supporter of the MetaBrainz Foundation. By far: Google has donated more than $366,000!

THANK YOU GOOGLE. Your support really helps us along!

Summer of Code ’16 with Picard

Hi! I’m Rahul Raturi, GSoC participant for Picard. This was my first GSoC, and it’s been a pretty awesome experience. Following is the overview of my project.

About the project

The outline of the project is to allow searching for albums, artists and tracks from within Picard. This avoids switching back and forth between web browser and Picard for searching, say release. If Picard fails to auto tag a file usual flow to tag the file with correct metadata is to first select the file, then click on “Lookup in Browser”, then search correct release, and load it into Picard by clicking the green “Tagger” button. In some systems, the “Tagger” button wouldn’t show, which was also a nuisance. With this patch, the entities can be searched and optionally loaded into Picard using built-in search dialogs, so no application switching.

Search dialogs

Picard already provides search options (through a web browser) for three entities; namely track, artist, and album. So I’ve built search dialogs for these three.

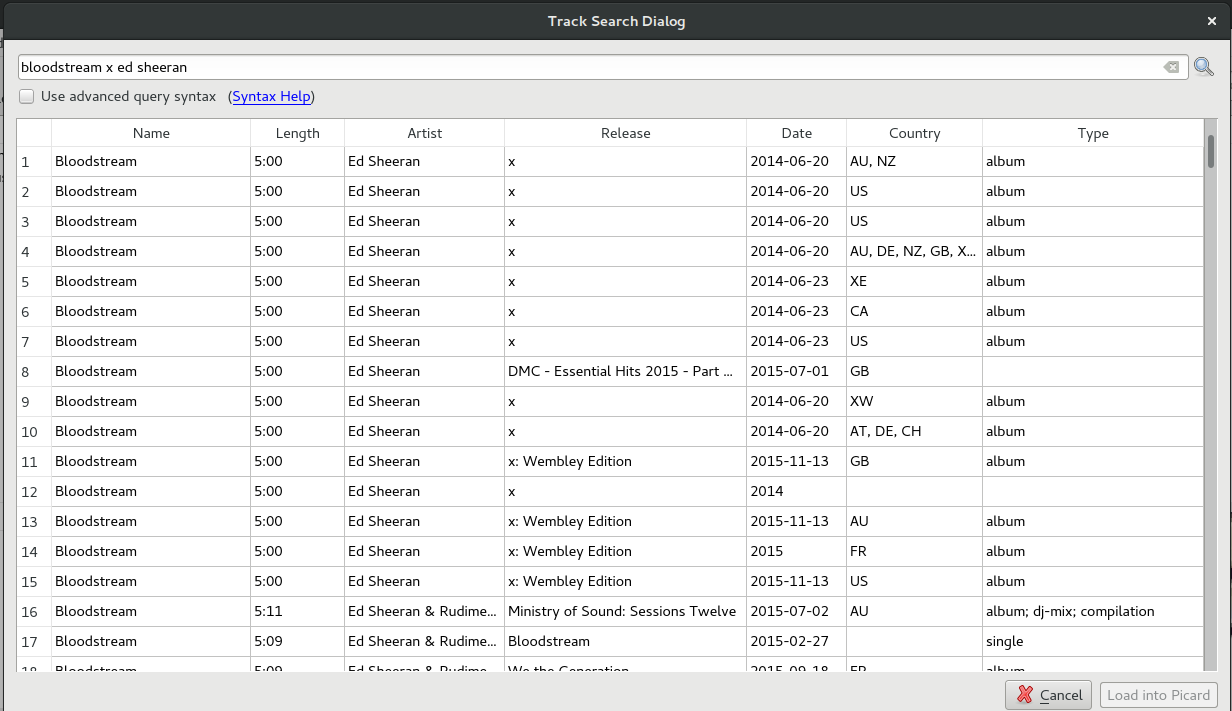
  1. Track Search Dialog — Searches for tracks and allows optionally loading corresponding album back into Picard. track_dialog
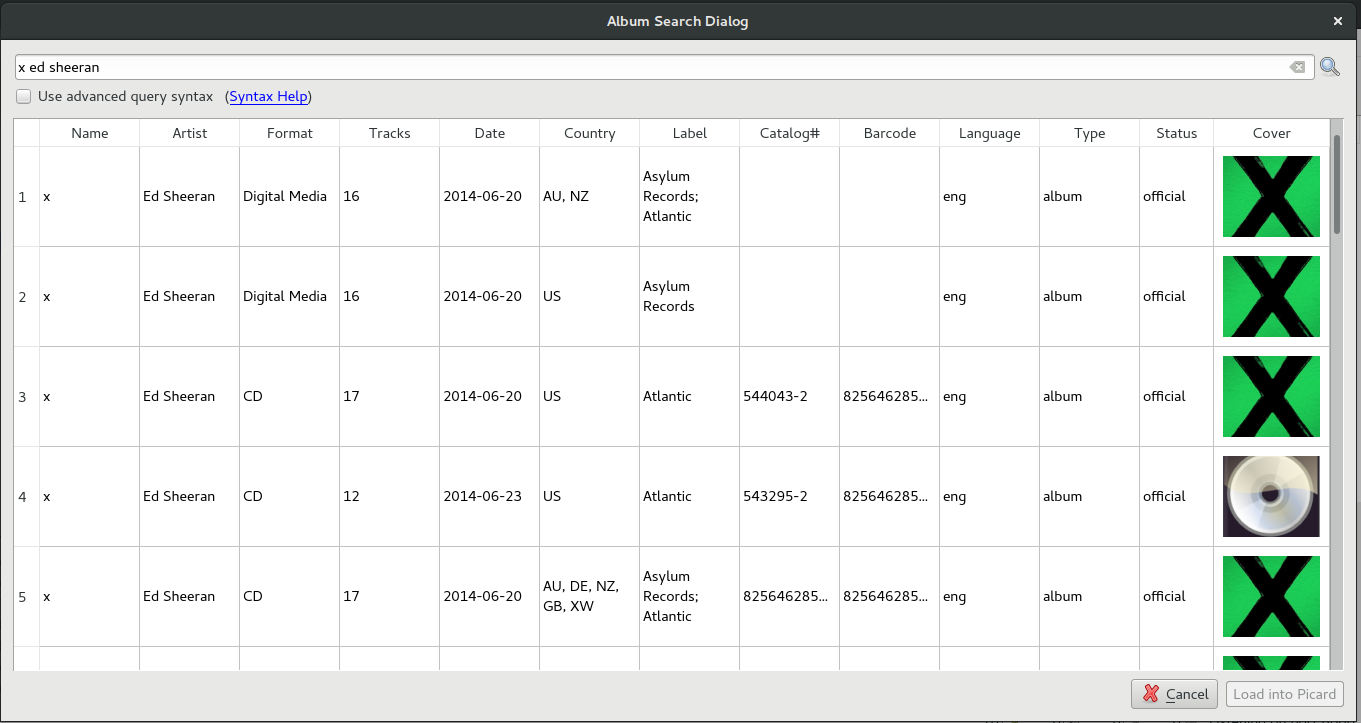
  2. Album Search Dialog — Searches albums and optionally allows loading the selected one into Picard. Screenshot from 2016-08-15 17-08-09
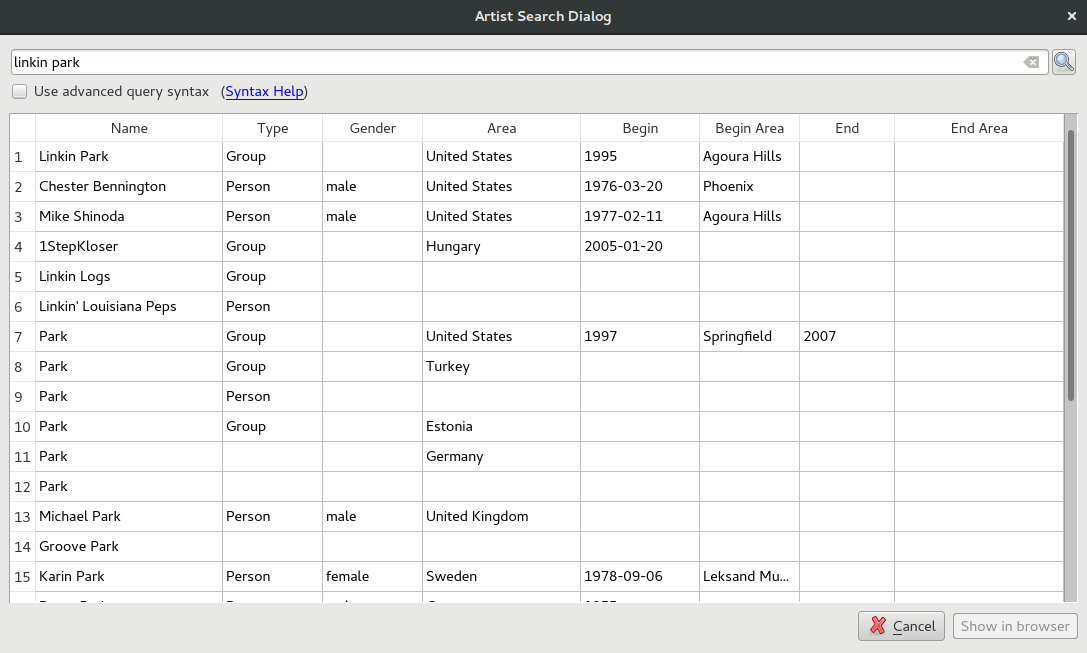
  3. Artist Search Dialog —  Displays basic information about the artists. To get more information about the selected artist, there’s an option to lookup him/her in browser. Screenshot from 2016-08-20 15-55-42

Searching similar tracks/releases

This is another important part of the project. Sometimes Picard fails to auto tag a file (or a cluster), or incorrectly tag it. These dialogs may prove useful here. To get expected data, right click on the file (should be in “Unmatched Files” cluster), and select “Search for similar tracks…”. The track search dialog would pop up, and expected release can be looked up there. Same procedure is for searching clusters.

Links to my work

Each PR is based on the previous one. A new dialog in each, plus some improvements to existing dialog. For trying the dialog, clone the artist search branch, until it gets merged into master. It has the most recent changes.

Note: To use these dialog for searching, an option in User Interface setting about built-in search needs to be enabled.

Conclusion

It was quite fun doing this project. Thanks to Michael Wiencek (mentor) for the guidance and leniency :). Also the Picard team for the reviews. I look forward to contribute more to Picard, now that I’ve a better understanding of the code. Also for another Summer of Code.

Schema change release: What happened?

Now that we’ve finally finished the schema change release, I wanted to give an account of what happened in this arduous process. Before I dive into the details, I want to offer a picture that best sums up our current situation and challenges:

personal-container-mngmnt3

The shipping container is MusicBrainz and the boat is our hosting infrastructure. This picture perfectly describes the sort of challenges we’ve faced over the past few days. 🙂

Here is what happened:

Because the site was recently running slow and our search servers kept crashing, Zas and I were not available to help Bitmap prepare for the schema change release. This long process was left to Bitmap and Gentlecat to take care of on their own. We quickly realized that we were not ready for the release when the due date came and thus we delayed one week.

Sunday 22 May

Finally we were ready to proceed with the Postgres 9.5 upgrade. Once we started the process, we kept running into small problems that we didn’t get in our test setups. We do not have access to enough infrastructure to have a complete clone of our production environment, so we can only do so much to prepare for all the things that might happen when we run upgrades on our production servers.

All the while we attempted to start the upgrade, our backup database server was running much slower than anticipated. In the end we figured out that a step for optimizing the database (analyzing it) wasn’t carried out. During this time the site was really slow/unusable, but by the time the problem became apparent we had started the upgrade and could not turn back.

Once the upgrade was done, optimizing the database took much much longer than usual: 3 hours! This process wasn’t started until about 1am local time, which made for a very long night before that process finished. And even then we hit snags and had to start over a couple of times. At about 4:30am we had the site running on Postgres 9.5 in read only mode. The plan was to rest and start the schema change release in the morning.

Monday 23 May

Of course we had spent all of our time working on the Postgres upgrade and site stability, so our document that we use to plan the schema change was not in place. We spent the day preparing this and other bits for the release. To get an appreciation for what this document looks like, have a look! Note that some steps could be instant, others might take hours to carry out. Others might involve a sub-step or 20 not included in the document.

In the evening we were ready to make the change. By this point our backup DB was performing much better, so the read-only site worked acceptably. Thus, we started the release. Overall, the actual release process was reasonably smooth – we hit a few snags and had to do a lot of waiting for our slow servers. At about 1am in the morning things were finally complete. We proceeded with our sanity checks to make sure things went smoothly and all of them passed.

We proceeded to put the site into read-write mode and immediately saw portions of Postgres crashing, which is really bad. With community feedback we quickly deduced that some write operations were causing Postgres back-end processes to crash. We went back to read-only mode on the site and things stabilized and we finally went to bed at 3am.

Tuesday 24 May

In the morning we quickly found the source of database trouble with the help from the Postgres people on IRC. Thanks for the swift help Johto! We found that the steps for installing the updated third party extensions into Postgres had not completed correctly. Repeating the steps by hand fixed this problem.

Sadly yesterday morning we got an email informing us that our Live Data Feed replication stream had become corrupted. 🙁 This was heartbreaking news to us, since it means a great inconvenience to all of our Live Data Feed users. We immediately split into two teams: Zas, chirlu and myself to fix the root cause of the issue and Bitmap to investigate fixing the stream.

I proceeded to setup a test environment was able to quickly reproduce the problem. Zas and chirlu were an amazing support team Googling issues as I came across them. Within fairly short time we fixed the problem and deployed the fix to our database server. The problem was caused by a bug in a piece of code that we’ve been using for 13 years! A change in Postgres caused this bug to actually become a problem and corrupt our replication feed. 🙁

Once the problems were fixed we needed to initiate a new data dump and check to make sure the replication stream is working correctly. Of course we found a problem that we fixed and re-started the process to dump the data. Loads of hurry-up-and-wait situations to try our patience!

When we were satisfied that things were working correctly we re-enabled the site as read-write at about 1am and allowed people to continue editing. Exhausted we stumbled into bed waiting for data dumps to sync out to the FTP site.

Wednesday 25 May

Today Bitmap was flying home and as soon as WiFi became available on his flight he started working and helping with putting the schema change to bed. We’ve verified that everything is working as expected. At last this saga comes to and end and we can all take a break and catch up on sleep!

Thank you for your patience through all of this.