Replication update: Do you have a DB that could help us?

In my post from yesterday I talked about our continuing struggle to fix our replication stream. Overnight we learned two new things:

  1. The lengthy hard drive recovery process has failed and yielded no useful results. 🙁
  2. We have a working DB diff program in place that allows us to create missing replication packets from two DBs at known packet numbers.

#2 is a great step forward in fixing our replication stream, but we’re missing a specific replicated database at a specific point in time. If you have a replicated database, please read on and see if you can help us:

  1. Is your database at replication packet 99847? The way to find out your current replication sequence is to look in slave.log in your server directory or to issue the query
    select current_replication_sequence from replication_control;

    at the SQL prompt.

  2. Do you have a complete replicated MusicBrainz database, including the cover_art_archive schema?
  3. Are you willing to make a dump of the DB and send it to us?
  4. Do you have a fast internet connection to make #3 possible?

If you’ve answered yes to all of the above, please send email to support at metabrainz dot org.

Thanks!


Move to NewHost and Replication Update

It has been a long week since our move to the new hosting provider in Germany. Our move across the Atlantic worked out fairly well in the grand scheme of things. The new servers are performing well, the site is more stable and we have a modern infrastructure for most of our projects.

However, such moves are not without problems. While we didn’t encounter many problems, the most significant one we did encounter was the failure to copy two small replication packets off the old servers. We didn’t notice this problem until after the server in question had been decommissioned. Ooops.

And thus began a recovery effort that is almost worthy of a bad Hollywood B-movie plot. Between myself traveling and the team finishing the most critical migration bits, it took 2 days for us to realize the problem and find a volunteer to fetch the drives from the broken server. Only in a small and wealthy place such as San Luis Obispo, could a stack of recycled servers sit in an open container for 2 days and not be touched at all. My friend collected the drives and immediately noticed that the drives were damaged in the recycling process, which isn’t surprising. And we can consider ourselves really lucky that this drive didn’t contain private data — those drives have been physically destroyed!

Since then, my friend has been working with Linux disk recovery tools to try and recover the two replication packets off the drive. Given that he is working with a 1TB drive, this recovery process takes a while and must be fully completed before attempting to pull data off the drive. For now we wait.

At the same time, we’re actively cobbling together a method to regenerate the lost packets. In theory it is possible, but it involves heroic efforts of stupidity. And we’re expending that effort, but so far, it bears no fruit.

In the meantime, for all of the people who use our replicated (Live Data) feed — you have the following choices:

  1. If you need data updates flowing again as soon as possible, we strongly recommend importing a new data set. We have a new data dump and fresh replication packets being put out, so you can do this at any time you’re ready.
  2. If the need for updates is not urgent yet and you’d rather not reload the data, sit tight. We’re continuing our stupidly heroic efforts to recover the replication packets.
  3. Chocolate: It really makes everything better. It may not help with your data problems, but at least it takes the edge off.

We’re terribly sorry for the hassle in all of this! Our geek pride has been sufficiently dinged that our chocolate coping mechanisms will surely cause us to put on a pound or two.

Stay tuned!

UPDATE 1: The first recovery examination has not located the files, but my friend will do a second pass tomorrow and turn over file fragments to us that might allow us to recover files. But that won’t be for another 8 hours or so.

Final sprint towards NewHost

So tomorrow is the day when the old servers at Digital West will be put to rest. Our developers and system administrator have been hard at work over the last few weeks (and especially the last few days!) getting everything ready for a hopefully smooth transition to hosting everything at Hetzner in Germany.

The vast majority of our sites and services are in fact already being served from Germany, but the largest one—musicbrainz.org—remains in the US for another night.

Our transition of the final services, such as musicbrainz.org, has already started, but the very last sprint of moving the remaining bits over will start tomorrow, November 8th, at around 6 AM EST / noon UTC / 13:00 CET and will follow the plan laid out in this Google document:
https://docs.google.com/document/d/1MgqZ4hiKC0MZJ400ZCOD8JlcjBjh4GNpakauf51YKQQ/edit?usp=sharing

Expect some downtime, plenty of read-only time, and general wonkiness as we get the last gears set in place to hopefully keep us running smoothly for the next several years to come!

Server update, 2016-10-24

Today we have more URL cleanup and general link fixes from chirlu & yvanz. Thanks to those two again. 🙂 This’ll be the last musicbrainz-server release before we move to our new hosting facility. But that move should be done within two weeks, so hopefully the next release won’t be delayed. Thanks again for your patience.

The git tag is v-2016-10-24.

Bug

  • [MBS-7164] – URL cleanup doesn’t allow iTunes “Song” download links
  • [MBS-9044] – iTunes: cleanup “geo.itunes” and block/cleanup “linkmaker.itunes” links

Improvement

  • [MBS-6314] – iTunes sidebar links should specify country
  • [MBS-8802] – Clean up iTunes audiobook and podcast URLs
  • [MBS-9079] – Clean up Wikidata URLs with “/entity”

Task

  • [MBS-8269] – Disallow Commons gallery pages and categories
  • [MBS-9078] – Improve URL cleanup for Wikimedia Commons
  • [MBS-9087] – Link to current VIAF URL format

Server update, 2016-10-10

With a looming deadline for switching to our new hosting facilities (early November), we didn’t have any release last month, and this one is several days late. But we’ve got some good contributions from chirlu and yvanz, especially in the area of URL validation and cleanup, which we’re finally releasing. Much of yvanz’s work has been to refactor our URL cleanup code so that it’s stricter and more robust. Thanks, chirlu & yvanz! You can view the complete changelog below.

The git tag is v-2016-10-10.

Bug

  • [MBS-8744] – Block Generasia URLs from Releases
  • [MBS-9069] – Submitting cover art with a long comment fails silently

Improvement

  • [MBS-8796] – Set a referrer policy for HTTPS pages
  • [MBS-9012] – New Discogs image URLs need cleaning up into release URLs
  • [MBS-9053] – Clean up commons.m.wikimedia.org into the non-mobile site
  • [MBS-9072] – Verify that tport is an integer

Task

  • [MBS-5733] – Allow “otherdatabases” to be validated in URLCleanup
  • [MBS-5736] – Test that the JavaScript catches bad URL entries
  • [MBS-6378] – Add tests for validationRules constraints in URLCleanup.js

New MusicBrainz test VM available

There is a new test VM available for anyone who would like to try the latest, possibly not fully debugged, VM. I’m not sure why the VM is nearly 20GB larger than the previous one, while containing roughly the same stuff, but that is what we’re stuck with for this test. I’ll try harder to minimize the size for the final build.

Grab the VM here.

Read these Usage tips.

IMPORTANT: Please ignore the usage tips published on the wiki — they do not apply to this release. For the next release I’ll try and match more of the characteristics of the last version. Do read the usage tips above!

File a bug here.

Server update, 2016-08-29

This is another small release containing URL relationship fixes, so I’ll let the changelog speak for itself. 🙂 Thanks again to yvanz and chirlu for their contributions. The git tag is v-2016-08-29.

Bug

  • [MBS-8793] – Query string is not removed from Twitter links
  • [MBS-9048] – Untouched obsolete URL relationships trigger errors in the editing process
  • [MBS-9057] – ISE for artist with PayPalMe URL

GSoC ’16 + ListenBrainz = fun :)

Hello,

I am Pinkesh Badjatiya and I have been working on ListenBrainz as part of GSoC ’16. I was largely involved in implementing the most requested features in ListenBrainz.
I began my journey with MetaBrainz not long before the Final Organization list was out. I started with MusicBrainz but moved quickly to ListenBrainz, and have been working on it since then.

About the project

The project consisted of creating a proxy scrobbling API similar to last.fm’s which could be used by existing desktop clients to submit listens to listenbrainz.org. I submitted my initial idea, that involved creating a new API along with few other optional features that were very much required (import, export, etc.).
The project made its way through the approval process, and I worked with ruaok (my mentor) & alastairp to get important things done. Yey!

Here are some of the snapshots of the my journey with ListenBrainz.

API_compat

ListenBrainz already had its own API which can be used to fetch/submit listens but all the existing clients that support scrobbling to last.fm use the ws.audioscrobbler.com’s API. To add support for these clients, I ended up creating a proxy API, api_compat (as in “compatible API”), that translates every request that is sent to “api.listenbrainz.org/2.0/” in the native format. This is an additional API which can be used along with the existing native ListenBrainz’s API.

This was largely the main goal of my project proposal. The instructions for scrobbling using Audacious are attached along with the source code.

Import lastfm-backup

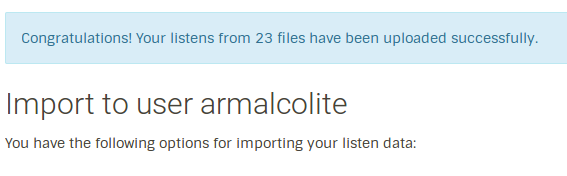
The import page now allows users to import listens from the last.fm scrobbles or from the backup file which was downloaded from the older version of the last.fm website.
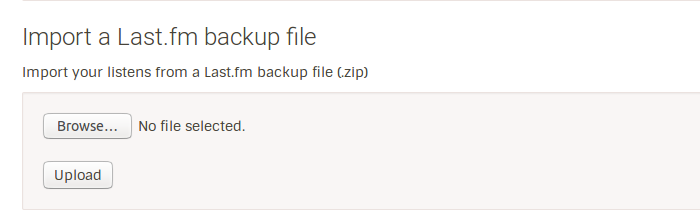
import_backup On successful import of listens from backup, you’ll get the following notification.import_success

Export listens

This allows users to export the listens from the listenbrainz.org website. This is useful for users who want to keep track of their listen history offline as well.
The export feature can be accessed from the drop-down menu.
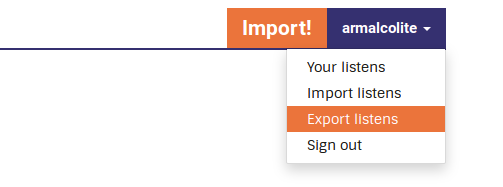
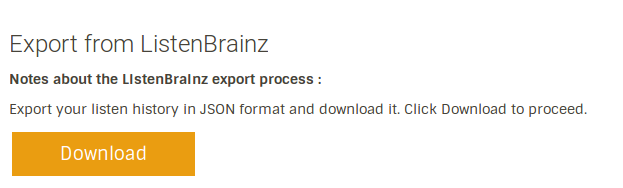
export_dropdown_menuexport_page

Playing Now

With the support for API-Compat, the support for currently playing song was needed. This keeps the currently playing song on the website in sync with your favourite player.
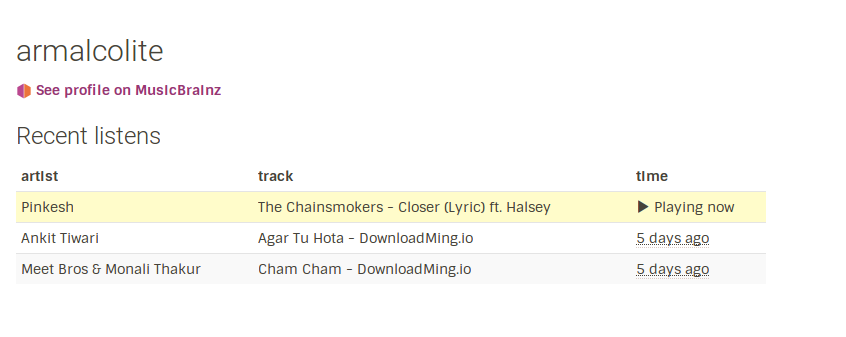
playing_now

Import scraper uses audioscrobbler API

I also worked on updating the import scraper which now use the ws.audioscrobbler.com‘s API allowing users to import without opening their last.fm profiles. This also provides other useful track information to ListenBrainz.

Migrate to PostgreSQL

Another important change to ListenBrainz was how it stored listens. We moved from using Cassandra to PostgreSQL. Cassandra was fast and effective but getting more information other than the user’s listens (ex. generating statistics) was not possible. So we switched to Postgres + Redis. This opened more possibilities for future.

Experience

After 3.5 months, I ended up with 15 merged and 3 closed PR’s and a bunch of features for ListenBrainz that improved its look and feel.

My pull requests: https://github.com/metabrainz/listenbrainz-server/pulls?utf8=%E2%9C%93&q=is%3Apr%20author%3Apinkeshbadjatiya%20

I have worked on quite a lot of varied things in the past 4 months. A lot of them were actually not the part of the GSoC proposal but they were done largely in the same timeline or were optional targets, so I suppose they would count significantly towards GSoC.
I worked largely with alastairp, ruaok and Gentlecat. Gentlecat helped improve my coding style by providing feedback on my PR’s. I worked with alastairp and ruaok regarding the ideas/suggestions on how to address a problem and its possible solutions. It was a interesting experience working with the community and getting to know about MetaBrainz. Now that my understanding of the project and the community has increased, I look forward to making some great contributions!

Conclusion

In short, ListenBrainz went through a hell lot of changes in the past 4 months. If you were waiting for it to improve before using it, then now is the time that you should try it. I bet you’ll love its new look and you won’t be disappointed. 😀
Summer of Code ’16 with Picard

Hi! I’m Rahul Raturi, GSoC participant for Picard. This was my first GSoC, and it’s been a pretty awesome experience. Following is the overview of my project.

About the project

The outline of the project is to allow searching for albums, artists and tracks from within Picard. This avoids switching back and forth between web browser and Picard for searching, say release. If Picard fails to auto tag a file usual flow to tag the file with correct metadata is to first select the file, then click on “Lookup in Browser”, then search correct release, and load it into Picard by clicking the green “Tagger” button. In some systems, the “Tagger” button wouldn’t show, which was also a nuisance. With this patch, the entities can be searched and optionally loaded into Picard using built-in search dialogs, so no application switching.

Search dialogs

Picard already provides search options (through a web browser) for three entities; namely track, artist, and album. So I’ve built search dialogs for these three.

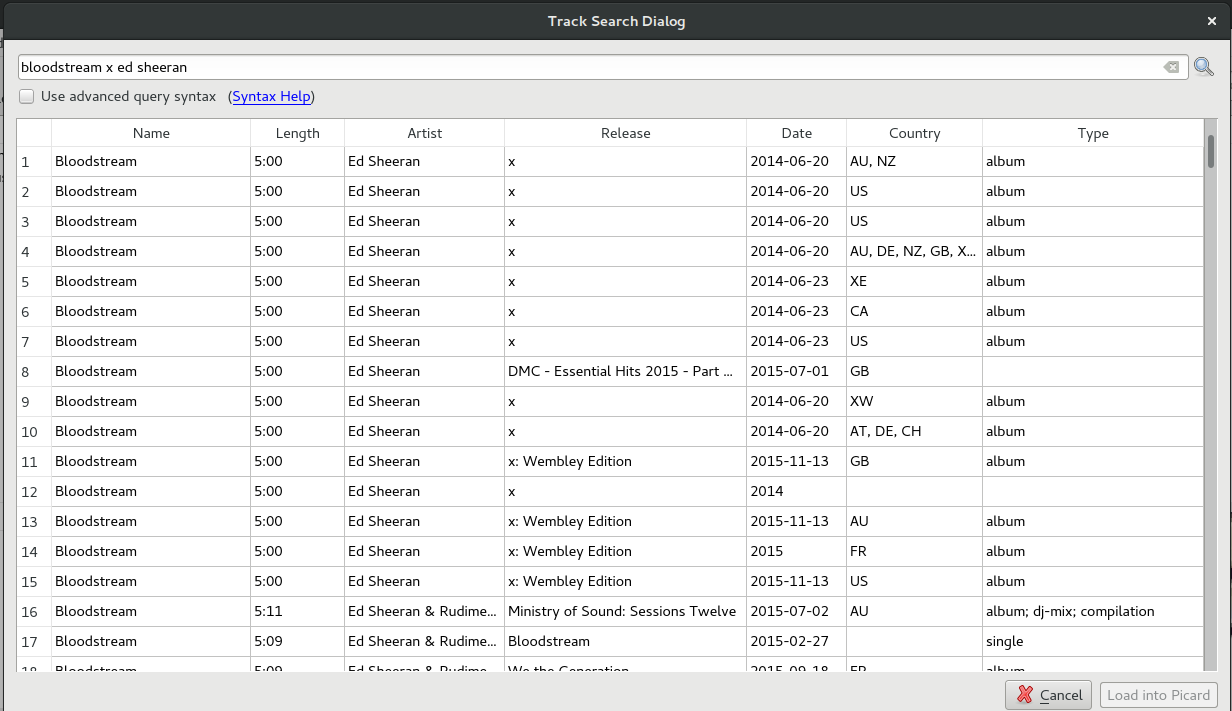
  1. Track Search Dialog — Searches for tracks and allows optionally loading corresponding album back into Picard. track_dialog
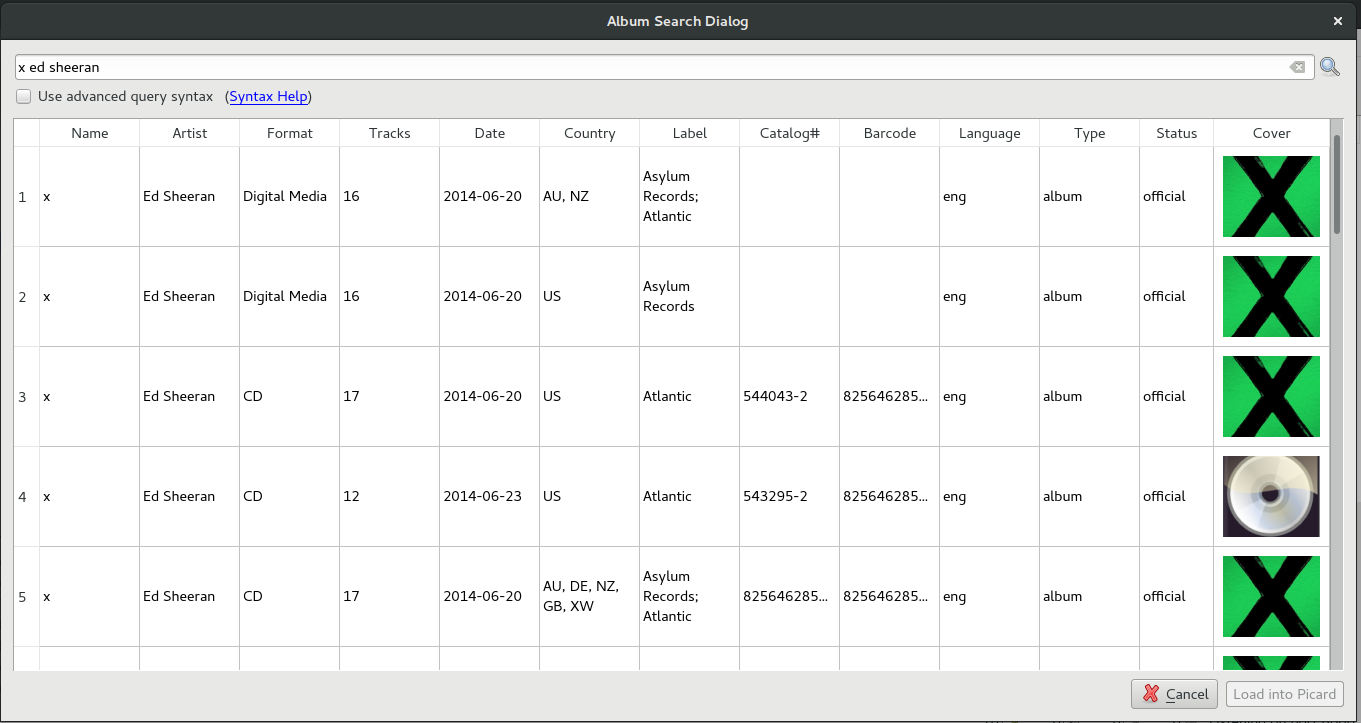
  2. Album Search Dialog — Searches albums and optionally allows loading the selected one into Picard. Screenshot from 2016-08-15 17-08-09
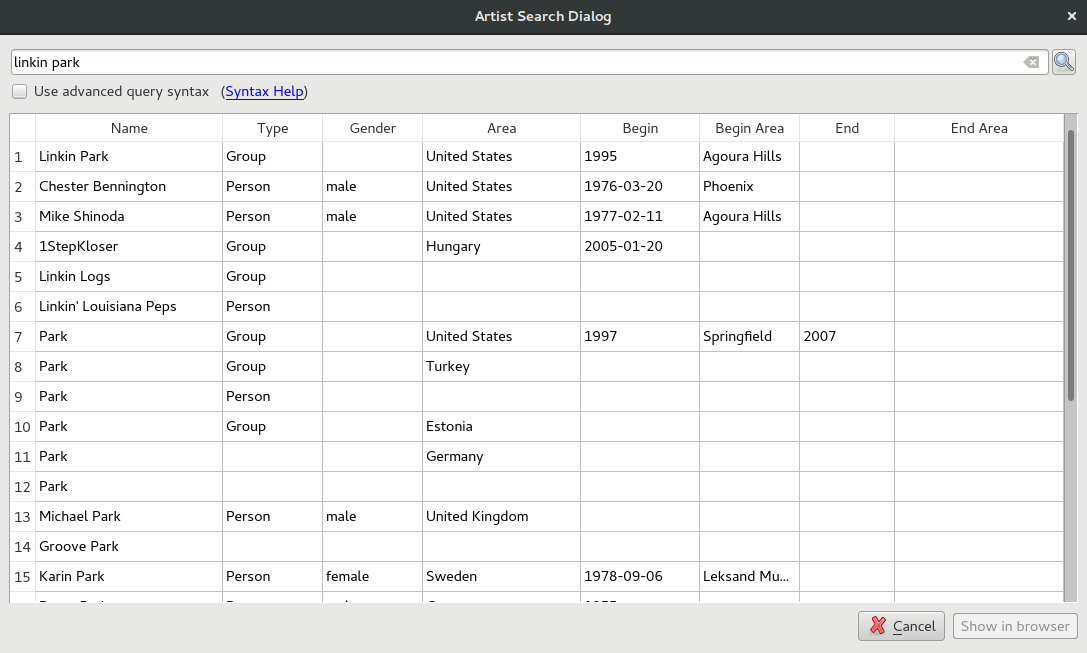
  3. Artist Search Dialog —  Displays basic information about the artists. To get more information about the selected artist, there’s an option to lookup him/her in browser. Screenshot from 2016-08-20 15-55-42

Searching similar tracks/releases

This is another important part of the project. Sometimes Picard fails to auto tag a file (or a cluster), or incorrectly tag it. These dialogs may prove useful here. To get expected data, right click on the file (should be in “Unmatched Files” cluster), and select “Search for similar tracks…”. The track search dialog would pop up, and expected release can be looked up there. Same procedure is for searching clusters.

Links to my work

Each PR is based on the previous one. A new dialog in each, plus some improvements to existing dialog. For trying the dialog, clone the artist search branch, until it gets merged into master. It has the most recent changes.

Note: To use these dialog for searching, an option in User Interface setting about built-in search needs to be enabled.

Conclusion

It was quite fun doing this project. Thanks to Michael Wiencek (mentor) for the guidance and leniency :). Also the Picard team for the reviews. I look forward to contribute more to Picard, now that I’ve a better understanding of the code. Also for another Summer of Code.

BookBrainz GSoC Gamification/Achievement System

Hi guys, I’m Max (AKA QuoraUK), a university student working with BookBrainz as part of Google Summer of Code. My project this summer has been to build a new gamification system, that introduces rewards for BookBrainz users and recognises their achievements. Here I will explain the system and the features I’ve implemented.

Overview

My original specification for the gamification system is here. To summarise, the idea behind gamification is to add game-like elements to the site in order to make it more engaging for users. The plan for the gamification of BookBrainz was:

  • Add badges and titles for users to earn on the BookBrainz site
  • Allow users to display badges and titles on their profile page
  • Encourage regular and high quality content

To implement this plan we have added 12 achievement tracks – once an achievement track is completed a title is unlocked. The artwork for the badges is currently “programmer art” and we are very open to other people designing replacements for them. This could be a part of this year’s Google Code-In. The achievements that will be available on launch are:

revisioncreator
Revisionist: Perform (1, 50, 250) Revision(s); Creator Creator: Create (1, 10, 100) Creator(s)
limitedpublisher
Limited Edition: Create (1, 10, 100) Edition(s); Publisher: Create (1, 10, 100) Publication(s)
pubcreatworker
Publisher Creator: Create (1, 10, 100) Publisher(s); Worker Bee: Create (1, 10, 100) Work(s)
runnerexplorer
Sprinter: Create 10 revisions in an hour; Fun Runner: Create a revision a day for a week; Marathoner: Create a revision a day for 30 days; Explorer: View (10, 100, 1000) Entities
timetrack
Time Traveller: Create an edition before it is released; Hot Off the Press: Create an edition within a week of release

All of these are unit tested and have unique badges for each tier on the track. If you would have already unlocked these achievements before the system was launched, you will earn them with your next revision/creation. Badge templates are available for developers to introduce new badges and adding achievements can be as simple as making a badge and adding a few lines of code.

Profile Page

profilednd
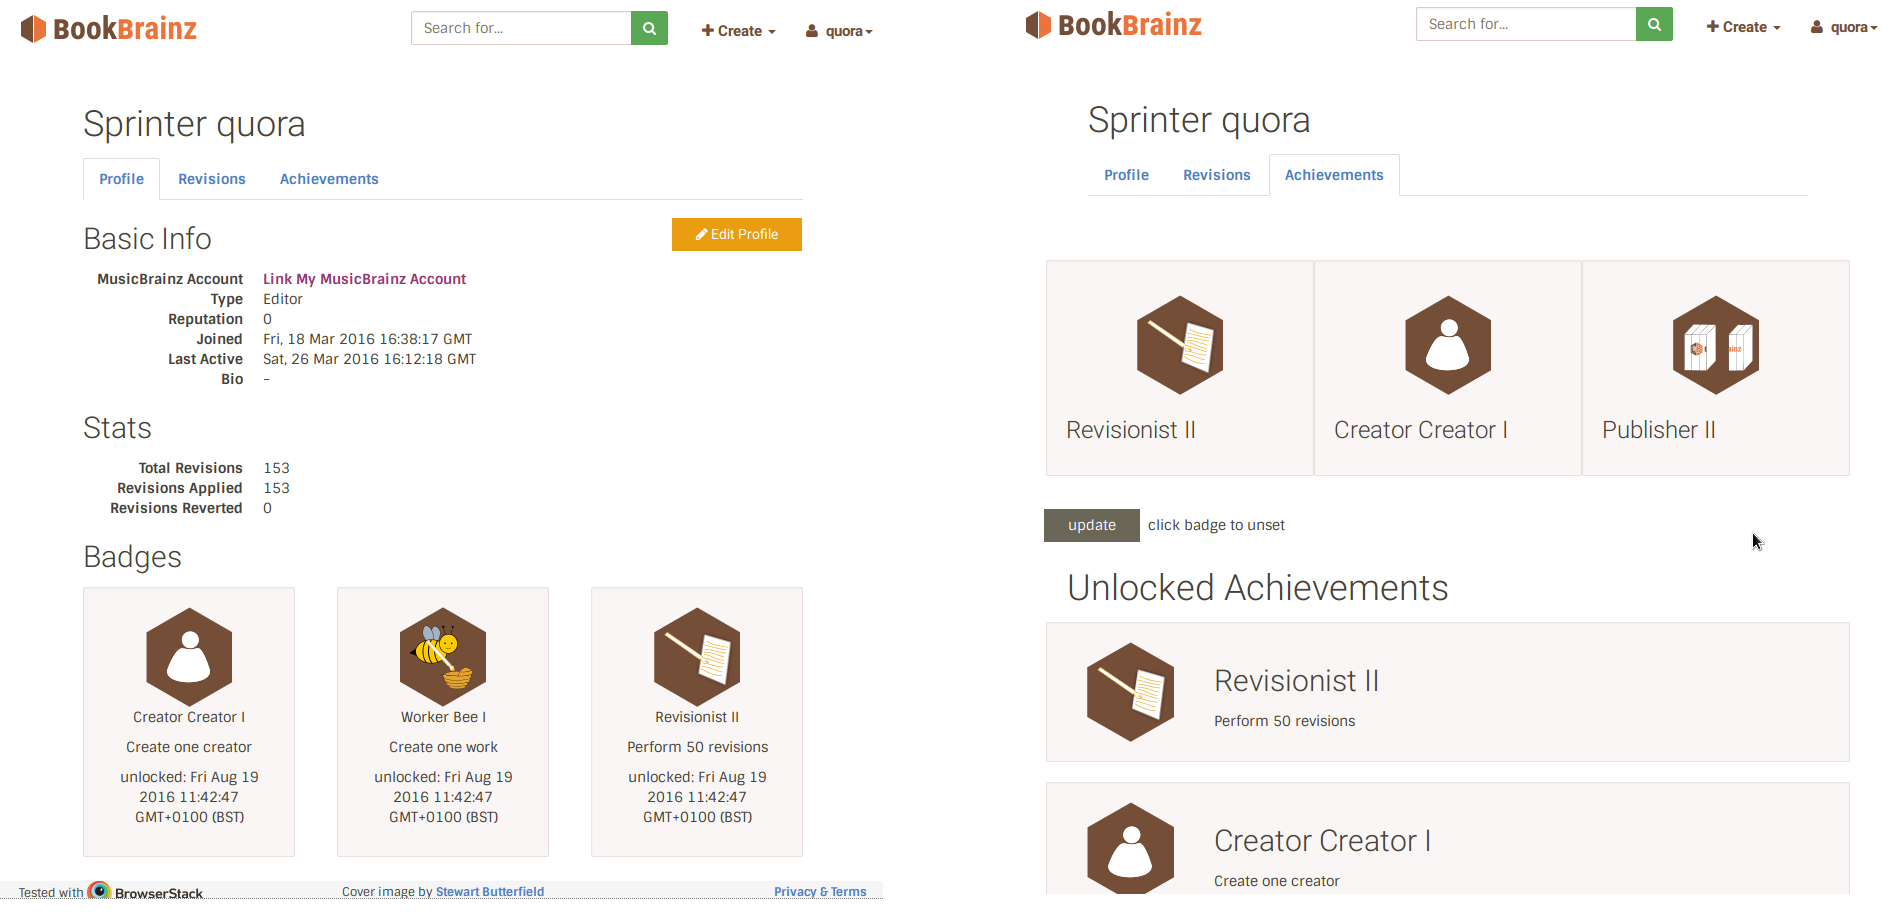
Profile Page, Drag and drop badge selector

The gamification system also brings some changes to the profile page. There is now a badge box which can contain your three favorite badges. Additionally, your selected title is shown next to your username. You can select your favorite badges in the new achievements menu on the profile, then drag and drop your favorites into the boxes. Titles can be selected by going to Edit Profile, and selecting them from the drop down menu.

Other Areas

2016-08-20_16-12-21
Achievement Alert

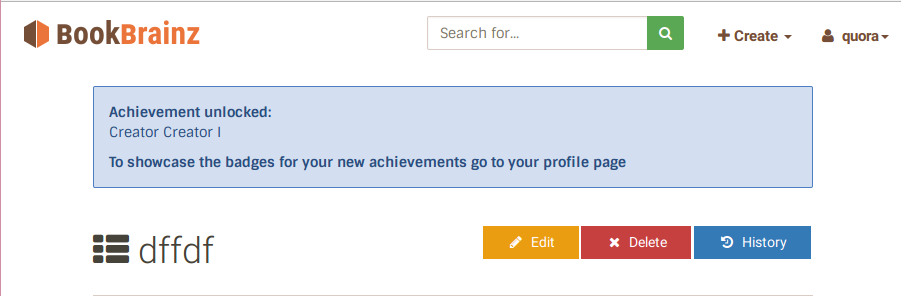
On creation of an entity or revision you will now see an alert if an achievement is unlocked. This will prompt you to go to your profile page and set the ones you want to display. Usernames in other areas of the site can be hovered over in order to see the title they have set.

Demonstration

Here is a demonstration video I’ve made for the system:
[youtube https://www.youtube.com/watch?v=XEZROTq1lY0]
Continue reading “BookBrainz GSoC Gamification/Achievement System”